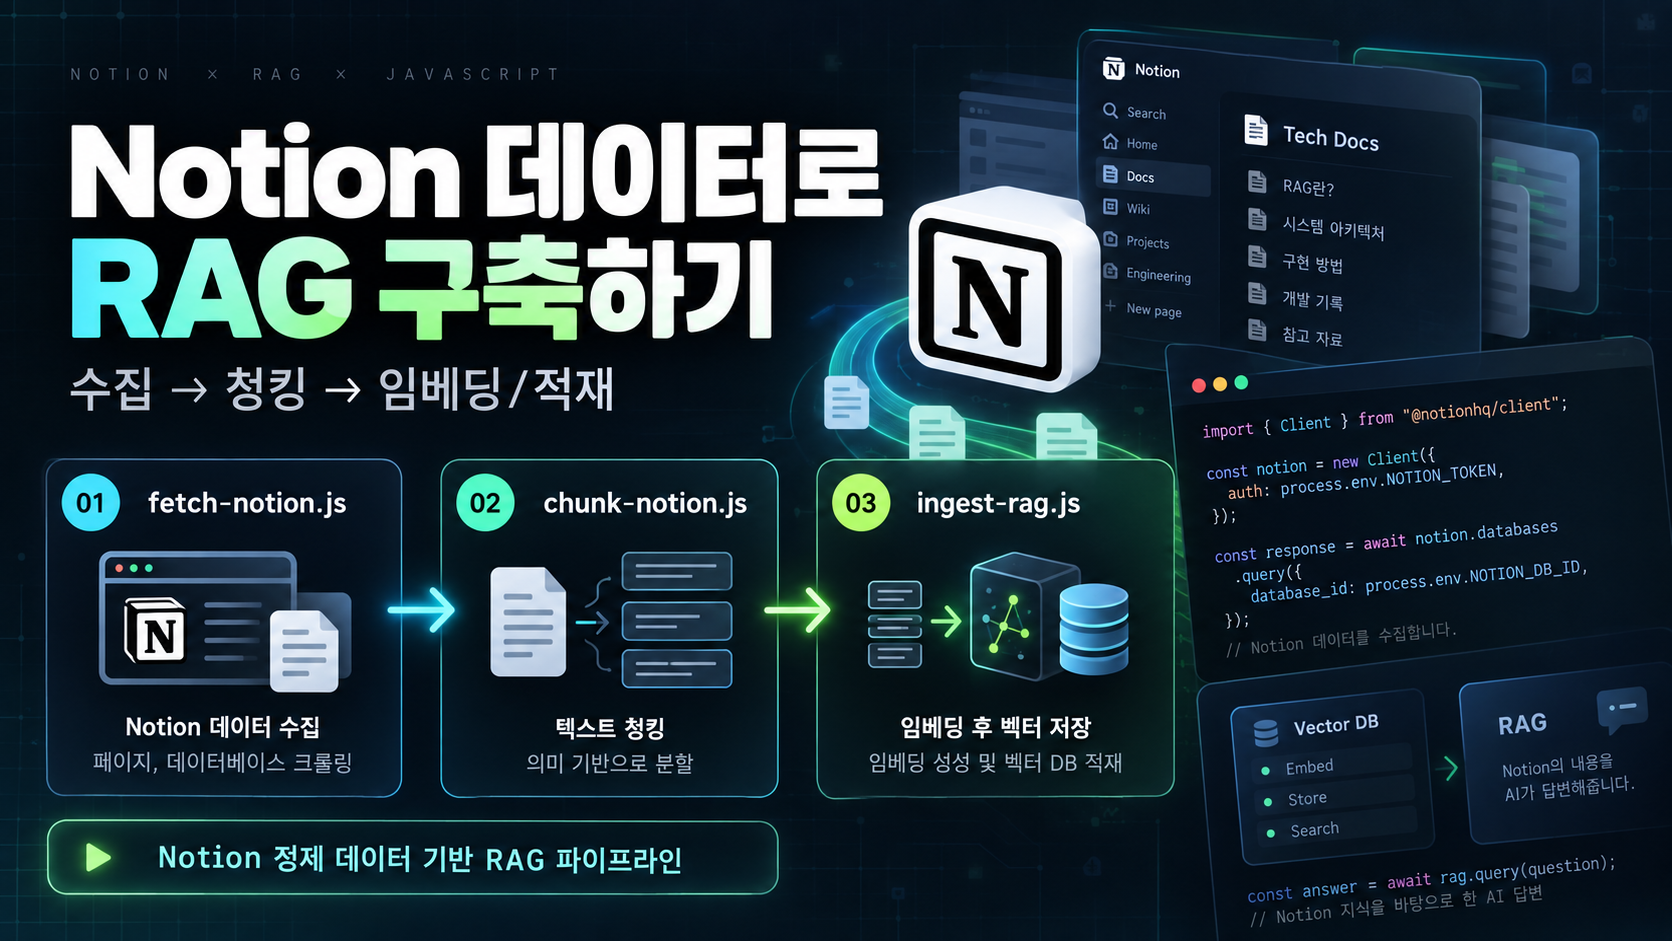
1. Notion 데이터 정재하기 (fetch-notion.js)
#!/usr/bin/env node
'use strict';

const fs = require('node:fs/promises');
const path = require('node:path');
const { chromium } = require('playwright');

// Teacher pages link to student help pages, so crawl the student roots first.
const ROOT_PAGES = [
	{
		audience: 'student',
		url: '',
	},
	{
		audience: 'teacher',
		url: '',
	},
];

const TARGET_HOST = '';
const PAGE_LOAD_WAIT_MS = 2500;
const NOISE_TEXTS = new Set([]);

const isTargetNotionUrl = (rawUrl) => {
	try {
		return new URL(rawUrl).hostname === TARGET_HOST;
	} catch {
		return false;
	}
};

const getNotionPageId = (rawUrl) => {
	try {
		const matches = [...new URL(rawUrl).pathname.matchAll(/[0-9a-f]{32}/gi)];
		return matches.length ? matches.at(-1)[0].toLowerCase() : null;
	} catch {
		return null;
	}
};

const cleanText = (rawText) =>
	rawText
		.split('\n')
		.map((line) => line.trim())
		.filter((line) => line && !NOISE_TEXTS.has(line))
		.join('\n');

const extractInternalLinks = async (page) => {
	const links = await page
		.locator('a')
		.evaluateAll((elements) =>
			elements.map((element) => element.href).filter(Boolean),
		);
	return links.filter(isTargetNotionUrl);
};

const extractNotionBlocks = async (page) => {
	const blocks = await page.locator('[data-block-id]').evaluateAll((elements) =>
		elements
			// Notion adds data-block-id to wrapper blocks as well as their children.
			// Keep only the innermost block to avoid storing the same text repeatedly.
			.filter((element) => !element.querySelector('[data-block-id]'))
			.map((element) => ({
				id: element.getAttribute('data-block-id'),
				text: element.innerText?.trim() || '',
			})),
	);

	return blocks
		.map((block) => ({
			...block,
			text: cleanText(block.text),
		}))
		.filter((block) => block.id && block.text);
};

const extractPageData = async (page, url) => {
	await page.goto(url, {
		waitUntil: 'domcontentloaded',
		timeout: 60_000,
	});
	await page.waitForTimeout(PAGE_LOAD_WAIT_MS);

	const rawTitle = await page.title();
	const title = rawTitle.replace(/\s*\|\s*Notion\s*$/i, '').trim();
	const rawText = await page.locator('body').innerText();
	const text = cleanText(rawText);
	const blocks = await extractNotionBlocks(page);
	const links = await extractInternalLinks(page);

	return { title, text, blocks, links };
};

const crawlPage = async ({ page, url, audience, visited, documents }) => {
	if (!isTargetNotionUrl(url)) return;

	const pageId = getNotionPageId(url);
	if (!pageId) {
		console.warn(`[${audience}] Skipping URL without a Notion page ID: ${url}`);
		return;
	}

	// 같은 Notion 페이지 ID는 URL 표기가 달라도 한 번만 수집
	if (visited.has(pageId)) return;
	visited.add(pageId);

	console.log(`[${audience}] Crawling: ${url}`);
	let result;
	try {
		result = await extractPageData(page, url);
	} catch (error) {
		console.error(`Failed to crawl ${url}: ${error.message}`);
		return;
	}

	if (result.text) {
		documents.push({
			audience,
			pageId,
			title: result.title,
			url,
			text: result.text,
			blocks: result.blocks,
		});
	}

	// Even pages with no readable body may link to pages that contain useful content.
	await result.links.reduce(
		(previous, link) =>
			previous.then(() =>
				crawlPage({ page, url: link, audience, visited, documents }),
			),
		Promise.resolve(),
	);
};

const main = async () => {
	const outputPath = path.resolve('data/notion-cleaned.json');
	console.log('Notion 수집 시작');
	console.log('실행 모드: headless');
	console.log(`출력 파일: ${outputPath}`);

	const browser = await chromium.launch({
		headless: true,
		...(process.env.CHROMIUM_EXECUTABLE_PATH
			? { executablePath: process.env.CHROMIUM_EXECUTABLE_PATH }
			: {}),
	});
	console.log('Chromium 브라우저 실행 완료');
	const page = await browser.newPage();
	const visited = new Set();
	const documents = [];

	try {
		// ROOT_PAGES 순서대로 재귀 수집
		await ROOT_PAGES.reduce(
			(previous, rootPage) =>
				previous.then(async () => {
					console.log(`[${rootPage.audience}] 루트 수집 시작: ${rootPage.url}`);
					const visitedBefore = visited.size;
					const documentsBefore = documents.length;
					await crawlPage({
						page,
						url: rootPage.url,
						audience: rootPage.audience,
						visited,
						documents,
					});
					console.log(
						`[${rootPage.audience}] 루트 수집 완료: 방문 ${
							visited.size - visitedBefore
						}페이지, 문서 ${documents.length - documentsBefore}개 추가`,
					);
				}),
			Promise.resolve(),
		);
	} finally {
		await browser.close();
		console.log('Chromium 브라우저 종료');
	}

	await fs.mkdir(path.dirname(outputPath), { recursive: true });
	await fs.writeFile(outputPath, JSON.stringify(documents, null, 2), 'utf8');

	console.log('Notion 수집 완료');
	console.log(`총 방문 페이지 수: ${visited.size}`);
	console.log(`저장 문서 수: ${documents.length}`);
	console.log(`저장 위치: ${outputPath}`);
};

main().catch((error) => {
	console.error('Notion fetch failed:', error);
	process.exitCode = 1;
});
실행 흐름
main()
 └─ crawlPage()
     ├─ extractPageData()
     │   ├─ cleanText()
     │   ├─ extractNotionBlocks()
     │   └─ extractInternalLinks()
     └─ 내부 링크를 다시 crawlPage()로 재귀 수집
2. 정재 데이터 청킹하기 (chunk-notion.js)
#!/usr/bin/env node

const fs = require('node:fs');
const path = require('node:path');
const { chunkNotionDocument } = require('../service/ai/rag/chunker');

const inputPath = path.resolve('data/notion-cleaned.json');
const outputPath = path.resolve('data/notion-chunks.json');

if (!fs.existsSync(inputPath)) {
	console.error(`입력 파일을 찾을 수 없습니다: ${inputPath}`);
	process.exit(1);
}

const documents = JSON.parse(fs.readFileSync(inputPath, 'utf8'));
if (!Array.isArray(documents)) {
	console.error('notion-cleaned.json 최상위 값이 배열이 아닙니다.');
	process.exit(1);
}

const chunks = documents.flatMap((document) =>
	chunkNotionDocument(document, {
		maxSize: 1000,
		overlap: 100,
		keepWholeBelow: 1000,
	}).map((chunk) => ({
		id: `notion_${chunk.pageId || 'unknown'}_${chunk.chunkIndex}`,
		document: chunk.text,
		metadata: {
			source: chunk.source,
			pageId: chunk.pageId,
			audience: chunk.audience,
			title: chunk.title,
			section: chunk.section,
			chunkIndex: chunk.chunkIndex,
			blockId: chunk.blockId,
		},
	})),
);

fs.mkdirSync(path.dirname(outputPath), { recursive: true });
fs.writeFileSync(outputPath, JSON.stringify(chunks, null, 2), 'utf8');

const chunkLengths = chunks.map((chunk) => chunk.document.length);
console.log(`입력 문서: ${documents.length}개`);
console.log(`생성 chunk: ${chunks.length}개`);
console.log(
	`chunk 길이(문자): 평균 ${Math.round(
		chunkLengths.reduce((sum, length) => sum + length, 0) /
			(chunkLengths.length || 1),
	)} / 최소 ${chunkLengths.length ? Math.min(...chunkLengths) : 0} / 최대 ${chunkLengths.length ? Math.max(...chunkLengths) : 0}`,
);
console.log(`출력 파일: ${outputPath}`);

documents.forEach((document) => {
	const documentChunks = chunks.filter(
		(chunk) => chunk.metadata.pageId === document.pageId,
	);
	console.log(
		`[${document.audience || '미지정'}] ${document.title || '제목 없음'}: ${documentChunks.length} chunk(s)`,
	);
});

const isNotionSectionHeading = (line) => {
	const normalized = line.trim();
	return Boolean(normalized && /^\d+(?:-\d+)*\.\s*\S/.test(normalized));
};

const splitLongLine = (line, maxSize) => {
	const sentences = line.match(/[^.!?。!?]+[.!?。!?]?/g) || [line];
	const pieces = [];
	let current = '';

	sentences.forEach((sentence) => {
		const candidate = current ? `${current} ${sentence.trim()}` : sentence.trim();
		if (candidate.length <= maxSize) {
			current = candidate;
			return;
		}
		if (current) pieces.push(current);
		current = '';

		const words = sentence.trim().split(/\s+/);
		words.forEach((word) => {
			const next = current ? `${current} ${word}` : word;
			if (next.length <= maxSize) {
				current = next;
			} else {
				if (current) pieces.push(current);
				current = word;
			}
			while (current.length > maxSize) {
				pieces.push(current.slice(0, maxSize));
				current = current.slice(maxSize);
			}
		});
	});
	if (current) pieces.push(current);
	return pieces;
};

/**
 * Chunk a Notion help document while keeping short documents intact,
 * respecting line/section boundaries, and adding title/section context.
 *
 * @param {{ title: string, text: string, source?: string, pageId?: string, audience?: string }} document
 * @param {{ maxSize?: number, overlap?: number, keepWholeBelow?: number }} [options]
 * @returns {{ text: string, source: string, pageId: string, audience: string, title: string, section: string, chunkIndex: number }[]}
 */
const chunkNotionDocument = (
	document,
	{ maxSize = 1000, overlap = 100, keepWholeBelow = 1000 } = {},
) => {
	if (!document?.text || !document.text.trim()) return [];

	const title = (document.title || '').trim();
	const lines = document.text
		.split('\n')
		.map((line) => line.trim())
		.filter(Boolean);
	if (title && lines[0] === title) lines.shift();
	const notionBlocks = Array.isArray(document.blocks) ? document.blocks : [];
	const getBlockId = (chunkText) => {
		const block = notionBlocks.find(({ id, text }) => {
			const normalizedText = text?.trim();
			const isPageRoot =
				String(document.pageId || '').replaceAll('-', '').toLowerCase() ===
				String(id || '').replaceAll('-', '').toLowerCase();
			return (
				normalizedText &&
				!isPageRoot &&
				chunkText.includes(normalizedText.slice(0, 80))
			);
		});
		return block?.id || document.pageId;
	};

	const originalText = document.text.trim();
	if (originalText.length <= keepWholeBelow) {
		const text = title && !originalText.startsWith(`${title}\n`)
			? `${title}\n\n${originalText}`
			: originalText;
		return [{
			text,
			source: document.url || '',
			pageId: document.pageId || '',
			audience: document.audience || '',
			title,
			section: '',
			chunkIndex: 0,
			blockId: getBlockId(text),
		}];
	}

	const chunks = [];
	let section = '';
	let current = '';
	let currentSection = '';
	let previousBody = '';

	const getPrefix = (chunkSection) =>
		[title, chunkSection].filter(Boolean).join(' > ');
	const getBodyLimit = (chunkSection) =>
		Math.max(1, maxSize - getPrefix(chunkSection).length - 2);

	const flush = () => {
		if (!current.trim()) return;
		const prefix = getPrefix(currentSection);
		chunks.push({
			text: prefix ? `${prefix}\n\n${current.trim()}` : current.trim(),
			source: document.url || '',
			pageId: document.pageId || '',
			audience: document.audience || '',
			title,
			section: currentSection,
			chunkIndex: chunks.length,
			blockId: getBlockId(prefix ? `${prefix}\n\n${current.trim()}` : current.trim()),
		});
		previousBody = current.trim();
		current = '';
	};

	lines.forEach((line) => {
		if (isNotionSectionHeading(line)) {
			section = line;
			if (current) {
				flush();
				currentSection = section;
				current = previousBody.slice(-overlap);
			} else if (current) {
				current += `\n${line}`;
			} else {
				currentSection = section;
			}
			return;
		}

		if (!current) currentSection = section;
		const bodyLimit = getBodyLimit(currentSection);
		const units = line.length > bodyLimit
			? splitLongLine(line, bodyLimit)
			: [line];

		units.forEach((unit) => {
			const candidate = current ? `${current}\n${unit}` : unit;
			if (candidate.length <= bodyLimit) {
				current = candidate;
				return;
			}

			flush();
			currentSection = section;
			const tail = previousBody.slice(-overlap);
			current = tail ? `${tail}\n${unit}` : unit;
			while (current.length > bodyLimit) {
				const piece = current.slice(0, bodyLimit);
				current = current.slice(Math.max(1, bodyLimit - overlap));
				const prefix = getPrefix(currentSection);
				chunks.push({
					text: prefix ? `${prefix}\n\n${piece}` : piece,
					source: document.url || '',
					pageId: document.pageId || '',
					audience: document.audience || '',
					title,
					section: currentSection,
					chunkIndex: chunks.length,
					blockId: getBlockId(prefix ? `${prefix}\n\n${piece}` : piece),
				});
				previousBody = piece;
			}
		});
	});
	flush();

	return chunks;
};
실행 흐름
입력 파일 확인
  ↓
notion-cleaned.json 읽기
  ↓
문서별 chunkNotionDocument() 실행
  ↓
청크 ID·metadata 생성
  ↓
notion-chunks.json 저장
  ↓
청크 통계 출력
3. 청킹 데이터 (ingest-rag.js)
#!/usr/bin/env node

/**
 * RAG Document Ingestion Script
 *
 * Reads markdown files, chunks them, embeds with OpenAI, and upserts to ChromaDB.
 *
 * Usage:
 *   node scripts/ingest-rag.js --school h_school --input ./docs/high_school/
 *   node scripts/ingest-rag.js --collection high_rag_docs_text-embedding-3-small --input ./docs/
 *   node scripts/ingest-rag.js --school h_school --input ./docs/high_school/ --file-only
 *
 * Options:
 *   --school <e_school|m_school|h_school>   School level (auto-derives collection name)
 *   --collection <name>                     Explicit ChromaDB collection name
 *   --input <path>                          Directory or glob of .md files (required)
 *   --model <id>                            Embedding model (default: text-embedding-3-small)
 *   --batch-size <n>                        Chunks per embed API call (default: 100)
 *   --chunk-size <n>                        Max chars per chunk (default: 1000)
 *   --chunk-overlap <n>                     Overlap chars between chunks (default: 200)
 *   --config <path>                         Config JSON path (default: ./configs/config.json)
 *   --chunker <markdown|length>             Chunking strategy (default: markdown)
 *   --replace                               Delete existing chunks for each source file before upserting
 *   --recreate                              Delete entire collection before creating (required to change metric)
 *   --metric <l2|cosine|ip>                 Distance metric for new collection (default: cosine)
 *   --file-only                             Save chunks to JSON file only — skip ChromaDB
 *   --json-input <path>                     Load pre-chunked JSON (skips markdown reading & chunking)
 *   --dry-run                               Print plan without ingesting
 */

const fs = require('fs');
const path = require('path');
const crypto = require('crypto');
const glob = require('glob');
const { embed } = require('../service/ai/embed');
const { CHUNKERS } = require('../service/ai/rag/chunker');

// ---------------------------------------------------------------------------
// Arg parsing
// ---------------------------------------------------------------------------

const parseArgs = (argv) => {
	const args = {};
	for (let i = 0; i < argv.length; i++) {
		const arg = argv[i];
		if (arg === '--dry-run') {
			args.dryRun = true;
		} else if (arg === '--replace') {
			args.replace = true;
		} else if (arg === '--recreate') {
			args.recreate = true;
		} else if (arg === '--file-only') {
			args.fileOnly = true;
		} else if (arg.startsWith('--')) {
			const key = arg.slice(2).replace(/-([a-z])/g, (_, c) => c.toUpperCase());
			args[key] = argv[i + 1];
			i++;
		}
	}
	return args;
};

const SCHOOL_PREFIX = Object.freeze({
	h_school: 'high',
	m_school: 'mid',
	e_school: 'element',
});

const resolveCollectionName = (args) => {
	if (args.collection) return args.collection;
	if (args.school) {
		const prefix = SCHOOL_PREFIX[args.school];
		if (!prefix) {
			throw new Error(
				`Unknown --school value "${args.school}". Use: h_school, m_school, e_school`,
			);
		}
		const model = args.model || 'text-embedding-3-small';
		return `${prefix}_rag_docs_${model}`;
	}
	throw new Error('Provide --school <level> or --collection <name>');
};

// ---------------------------------------------------------------------------
// Config loading (standalone: reads config.json, not global.*)
// ---------------------------------------------------------------------------

const loadProjectConfig = (configPath) => {
	const resolved = path.resolve(configPath || 'configs/config.json');
	if (!fs.existsSync(resolved)) {
		throw new Error(`Config file not found: ${resolved}`);
	}
	return JSON.parse(fs.readFileSync(resolved, 'utf8'));
};

// ---------------------------------------------------------------------------
// File discovery
// ---------------------------------------------------------------------------

const findMarkdownFiles = (input) => {
	const resolved = path.resolve(input);
	const stat = fs.existsSync(resolved) && fs.statSync(resolved);

	if (stat && stat.isDirectory()) {
		return glob.sync('**/*.md', { cwd: resolved, absolute: true });
	}
	return glob.sync(input, { absolute: true });
};

// ---------------------------------------------------------------------------
// Load pre-chunked JSON
// ---------------------------------------------------------------------------

/**
 * Reads a pre-chunked JSON file and returns { ids, texts, metadatas }.
 * Expected format: Array of { id, document, metadata: { source, chunkIndex, ... } }
 */
const loadJsonChunks = (jsonPath) => {
	const resolved = path.resolve(jsonPath);
	if (!fs.existsSync(resolved)) {
		throw new Error(`JSON input file not found: ${resolved}`);
	}
	const raw = JSON.parse(fs.readFileSync(resolved, 'utf8'));
	if (!Array.isArray(raw)) {
		throw new Error('JSON input must be an array of chunk objects');
	}
	const ids = [];
	const texts = [];
	const metadatas = [];
	for (const item of raw) {
		if (!item.id || !item.document || !item.metadata) {
			throw new Error(
				`Each chunk must have id, document, and metadata fields. Got: ${JSON.stringify(Object.keys(item))}`,
			);
		}
		ids.push(item.id);
		texts.push(item.document);
		// ChromaDB only supports primitive metadata values — serialize arrays to strings
		const normalizedMetadata = Object.fromEntries(
			Object.entries(item.metadata).map(([k, v]) => [
				k,
				Array.isArray(v) ? v.join(',') : v,
			]),
		);
		metadatas.push(normalizedMetadata);
	}
	return { ids, texts, metadatas };
};

// ---------------------------------------------------------------------------
// Stable chunk ID: deterministic from file path + chunk index
// ---------------------------------------------------------------------------

const makeChunkId = (filePath, chunkIndex) => {
	const hash = crypto
		.createHash('sha1')
		.update(filePath)
		.digest('hex')
		.slice(0, 8);
	const basename = path
		.basename(filePath, '.md')
		.replace(/[^a-zA-Z0-9_-]/g, '_');
	return `${basename}_${hash}_${chunkIndex}`;
};

// ---------------------------------------------------------------------------
// ChromaDB REST API helpers (bypasses JS client to avoid _type metadata issue)
// ---------------------------------------------------------------------------

const buildChromaApi = (
	rawHost,
	port,
	token,
	tenant = 'default_tenant',
	database = 'default_database',
) => {
	const base = rawHost.startsWith('http') ? rawHost : `http://${rawHost}`;
	const baseUrl = `${base}:${port}/api/v2`;
	const dbPath = `/tenants/${tenant}/databases/${database}`;
	const headers = {
		'Content-Type': 'application/json',
		...(token ? { Authorization: `Bearer ${token}` } : {}),
	};

	const request = async (method, endpoint, body) => {
		const url = `${baseUrl}${endpoint}`;
		const res = await fetch(url, {
			method,
			headers,
			...(body !== undefined ? { body: JSON.stringify(body) } : {}),
		});
		if (!res.ok) {
			const text = await res.text().catch(() => '');
			throw new Error(
				`ChromaDB ${method} ${endpoint} → ${res.status}: ${text}`,
			);
		}
		return res.json();
	};

	const getOrCreateCollection = (name, metric) =>
		request('POST', `${dbPath}/collections`, {
			name,
			get_or_create: true,
			...(metric ? { metadata: { 'hnsw:space': metric } } : {}),
		});

	const deleteCollection = (name) =>
		request(
			'DELETE',
			`${dbPath}/collections/${encodeURIComponent(name)}`,
		).catch((err) => {
			// Treat 404 as success (idempotent delete)
			if (/→ 404/.test(err.message)) return null;
			throw err;
		});

	const upsert = (collectionId, payload) =>
		request('POST', `${dbPath}/collections/${collectionId}/upsert`, payload);

	/**
	 * Delete all chunks whose `source` metadata matches any of the given paths.
	 * Uses ChromaDB where-filter: { source: { "$in": [...] } }
	 */
	const deleteBySource = (collectionId, sources) =>
		request('POST', `${dbPath}/collections/${collectionId}/delete`, {
			where: { source: { $in: sources } },
		});

	const count = (collectionId) =>
		request('GET', `${dbPath}/collections/${collectionId}/count`);

	return {
		getOrCreateCollection,
		deleteCollection,
		upsert,
		deleteBySource,
		count,
	};
};

// ---------------------------------------------------------------------------
// Embed in batches
// ---------------------------------------------------------------------------

const embedBatch = async (texts, aiConfig, model) => {
	return embed(texts, { config: aiConfig, model });
};

const embedInBatches = async (texts, batchSize, aiConfig, model) => {
	const allEmbeddings = [];
	for (let i = 0; i < texts.length; i += batchSize) {
		const batch = texts.slice(i, i + batchSize);
		process.stdout.write(
			`  Embedding batch ${Math.floor(i / batchSize) + 1}/${Math.ceil(texts.length / batchSize)} (${batch.length} chunks)...\n`,
		);
		const embeddings = await embedBatch(batch, aiConfig, model);
		allEmbeddings.push(...embeddings);
	}
	return allEmbeddings;
};

// ---------------------------------------------------------------------------
// Main
// ---------------------------------------------------------------------------

const main = async () => {
	const args = parseArgs(process.argv.slice(2));

	if (!args.input && !args.jsonInput) {
		console.error('Error: --input <path> or --json-input <path> is required');
		process.exit(1);
	}

	const model = args.model || 'text-embedding-3-small';
	const batchSize = parseInt(args.batchSize || '100', 10);
	const chunkSize = parseInt(args.chunkSize || '1000', 10);
	const chunkOverlap = parseInt(args.chunkOverlap || '200', 10);
	const dryRun = args.dryRun === true;
	const replace = args.replace === true;
	const recreate = args.recreate === true;
	const metric = args.metric || 'cosine';
	if (!['l2', 'cosine', 'ip'].includes(metric)) {
		console.error(
			`Error: --metric must be one of l2, cosine, ip (got "${metric}")`,
		);
		process.exit(1);
	}
	const fileOnly = args.fileOnly === true;
	const jsonInput = args.jsonInput || null;

	if (!jsonInput) {
		const chunkerKey = args.chunker || 'markdown';
		if (!CHUNKERS[chunkerKey]) {
			console.error(
				`Error: unknown --chunker "${chunkerKey}". Available: ${Object.keys(CHUNKERS).join(', ')}`,
			);
			process.exit(1);
		}
	}
	const chunkerKey = jsonInput ? null : args.chunker || 'markdown';
	const chunkFn = chunkerKey ? CHUNKERS[chunkerKey] : null;

	const collectionName =
		fileOnly && !args.school && !args.collection
			? null
			: resolveCollectionName({ ...args, model });

	// JSON output path: <collectionName>_<timestamp>.json
	const timestamp = new Date().toISOString().replace(/[:.]/g, '-').slice(0, 19);
	const nameBase =
		collectionName ??
		(args.input
			? `chunks_${path.basename(path.resolve(args.input))}`
			: `chunks_json_${path.basename(path.resolve(args.jsonInput))}`);
	const jsonOutputPath = path.resolve(
		'output',
		`${nameBase}_${timestamp}.json`,
	);
	const projectConfig = loadProjectConfig(args.config);

	const ai = projectConfig.AI || {};
	const aiConfig = {
		language: {},
		embedding: {
			provider: ai.provider || 'openai',
			model,
			apiKey: ai.apiKey,
			baseURL: ai.baseURL || undefined,
		},
	};

	console.log(`\nRAG Ingestion`);
	console.log(
		`  Collection : ${fileOnly ? '(file only — skipping ChromaDB)' : collectionName}`,
	);
	console.log(`  Model      : ${model}`);
	console.log(`  Chunk size : ${chunkSize} chars (overlap: ${chunkOverlap})`);
	console.log(`  Batch size : ${batchSize}`);
	console.log(`  JSON output: ${jsonOutputPath}`);
	console.log(
		`  Chunker    : ${jsonInput ? '(pre-chunked JSON)' : chunkerKey}`,
	);
	console.log(`  Replace    : ${replace}`);
	console.log(`  Recreate   : ${recreate}`);
	console.log(`  Metric     : ${metric}`);
	console.log(`  File only  : ${fileOnly}`);
	console.log(`  JSON input : ${jsonInput || '(none)'}`);
	console.log(`  Dry run    : ${dryRun}`);
	console.log();

	let ids, texts, metadatas;

	if (jsonInput) {
		// 1. Load pre-chunked JSON
		console.log(`Loading pre-chunked JSON: ${path.resolve(jsonInput)}`);
		({ ids, texts, metadatas } = loadJsonChunks(jsonInput));
		console.log(`Loaded ${ids.length} chunk(s) from JSON.\n`);
	} else {
		// 1. Find files
		if (!args.input) {
			console.error('Error: --input <path> or --json-input <path> is required');
			process.exit(1);
		}
		const files = findMarkdownFiles(args.input);
		if (files.length === 0) {
			console.error(`No .md files found at: ${args.input}`);
			process.exit(1);
		}
		console.log(`Found ${files.length} markdown file(s):`);
		files.forEach((f) => console.log(`  ${f}`));
		console.log();

		// 2. Chunk all files
		const allChunks = [];
		for (const filePath of files) {
			const content = fs.readFileSync(filePath, 'utf8');
			const relative = path.relative(process.cwd(), filePath);
			const chunks = chunkFn(content, {
				maxSize: chunkSize,
				overlap: chunkOverlap,
				source: relative,
			});
			allChunks.push(...chunks.map((c) => ({ ...c, filePath })));
			console.log(`  ${relative}: ${chunks.length} chunk(s)`);
		}
		console.log(`\nTotal chunks: ${allChunks.length}`);

		texts = allChunks.map((c) => c.text);
		ids = allChunks.map((c) => makeChunkId(c.filePath, c.chunkIndex));
		metadatas = allChunks.map((c) => ({
			source: c.source,
			chunkIndex: c.chunkIndex,
		}));
	}

	if (dryRun) {
		console.log('\nDry run — stopping before embed/upsert.');
		return;
	}

	// 3. Embed
	console.log('\nEmbedding...');
	const embeddings = await embedInBatches(texts, batchSize, aiConfig, model);

	// Always write JSON (embedding excluded) — skip if input was already a JSON file
	if (!jsonInput) {
		const jsonOutput = ids.map((id, i) => ({
			id,
			document: texts[i],
			metadata: metadatas[i],
		}));
		fs.mkdirSync(path.dirname(jsonOutputPath), { recursive: true });
		fs.writeFileSync(
			jsonOutputPath,
			JSON.stringify(jsonOutput, null, 2),
			'utf8',
		);
		console.log(
			`\nJSON saved: ${jsonOutputPath} (${jsonOutput.length} chunk(s))`,
		);
	}

	// 4a. File-only mode — skip ChromaDB
	if (fileOnly) {
		console.log('\nFile-only mode — skipping ChromaDB.');
		return;
	}

	// 4b. Upsert to ChromaDB
	const chroma = projectConfig.CHROMA || {};
	const chromaApi = buildChromaApi(
		chroma.host || 'localhost',
		chroma.port || 8000,
		chroma.token,
	);

	console.log('\nConnecting to ChromaDB...');
	if (recreate) {
		console.log(
			`  Recreating: deleting collection "${collectionName}" before create`,
		);
		await chromaApi.deleteCollection(collectionName);
	}
	const collectionData = await chromaApi.getOrCreateCollection(
		collectionName,
		metric,
	);
	const collectionId = collectionData.id;
	console.log(`  Collection ID: ${collectionId} (metric=${metric})`);

	// Delete existing chunks for each source file before upserting
	if (replace) {
		const sources = [...new Set(metadatas.map((m) => m.source))];
		console.log(
			`\nDeleting existing chunks for ${sources.length} source file(s)...`,
		);
		await chromaApi.deleteBySource(collectionId, sources);
		console.log('  Done.');
	}

	console.log('\nUpserting to ChromaDB...');
	for (let i = 0; i < ids.length; i += batchSize) {
		await chromaApi.upsert(collectionId, {
			ids: ids.slice(i, i + batchSize),
			embeddings: embeddings.slice(i, i + batchSize),
			documents: texts.slice(i, i + batchSize),
			metadatas: metadatas.slice(i, i + batchSize),
		});
		process.stdout.write(
			`  Upserted batch ${Math.floor(i / batchSize) + 1}/${Math.ceil(ids.length / batchSize)}\n`,
		);
	}

	const totalCount = await chromaApi.count(collectionId);
	console.log(
		`\nDone. Collection "${collectionName}" now has ${totalCount} document(s).`,
	);
};

main().catch((err) => {
	console.error('\nFatal:', err.message);
	process.exit(1);
});
스크립트 실행
node scripts/ingest-rag.js \
  --json-input data/notion-chunks.json \
  --replace \
  --collection aidt_notion_help_text-embedding-3-small
Backend Engineer