🌊 Delta Lake Beginner's Guide - Practical Edition (Part 1. Local Environment)
- Delta Lake Theory - 🌊 Delta Lake Beginner's Guide - Theory
- Delta Lake Practical Guide Part 1 - 🌊 Delta Lake Beginner's Guide - Practical Edition (Part 1. Local Environment)
- Delta Lake in Practice Part 2 - 🌊 Delta Lake Beginner's Guide - Practical Edition (Part 2. Utilizing the delta-spark library)
0. INTRO
- In the previous post , 🌊 Delta Lake Beginner's Guide - Theory, we covered the theoretical aspects of Delta Lake in detail. In this post, we will practice the features of Delta Lake in a Pyspark Docker Container environment.
- In this practice session, we use PySpark as the tool for handling data, and files of type delta are stored and managed in a local directory.
hyunsoolee0506/pyspark-cloud:3.5.1For Docker containers , I recommend using an image I have created separately, considering that you will be integrating with a cloud environment for future practice . However, for this local environment practice, it is fine to proceed using Google Colab.- For the practice session,
delta_data.zipwe used data from two CSV files located in the file below.
1️⃣ Setting up the Practice Environment
▪ 1) Create a Docker Container
/workspace/sparkConfigure the directory to be used as a volume on the user's computer to be mapped to the directory inside the container .
docker run -d \
    --name pyspark \
    -p 8888:8888 \
    -p 4040:4040 \
    -v [사용자 디렉토리]:/workspace/spark \
hyunsoolee0506/pyspark-cloud:3.5.1- After executing the command above,
8888you can access the juypter lab development environment by connecting to the port.
▪ 2) Install Library
- Install the libraries required for the practice.
hyunsoolee0506/pyspark-cloud:3.5.1Although they are already installed in the image, for Colab, you must install them by running the code below.
pip install pyspark==3.5.1 delta-spark==3.2.0 pyarrow findspark▪ 3) Pyspark Delta Lake Environment Setup
- https://docs.delta.io/latest/quick-start.html#set-up-apache-spark-with-delta-lake
- To use Delta Lake in PySpark, configure the relevant extensions when creating a SparkSession.
from delta import * from pyspark.sql import SparkSession import pyspark.sql.functions as Fbuilder = SparkSession.builder.appName("DeltaLakeLocal") \
.enableHiveSupport() \
.config("spark.sql.extensions", "io.delta.sql.DeltaSparkSessionExtension") \
.config("spark.sql.catalog.spark_catalog", "org.apache.spark.sql.delta.catalog.DeltaCatalog")
spark = configure_spark_with_delta_pip(builder).getOrCreate()
2️⃣ Create Database and Table
▪ 1) Create Database
deltalake_dbCreates a new database named.
spark.sql("CREATE DATABASE IF NOT EXISTS deltalake_db")spark.sql("SHOW DATABASES").show()
---
+------------+
| namespace|
+------------+
| default|
|deltalake_db|
+------------+
▪ 2) Create CSV type table
trainer_data.csvtrainerCreates a table to store the file's data .
- 테이블 이름 : trainer
- 스키마 :
  - id → INT
  - name → STRING
  - age → INT
  - hometown → STRING
  - prefer_type → STRING
  - badge_count → INT
  - level → STRING
query = f""" CREATE TABLE IF NOT EXISTS deltalake_db.trainer ( id INT, name STRING, age INT, hometown STRING, prefer_type STRING, badge_count INT, level STRING ) USING csv OPTIONS ( path '[trainer_data.csv 파일 경로]', header 'true', inferSchema 'true', delimiter ',' ) """spark.sql(query)
# 테이블 생성 확인
spark.sql("SHOW TABLES FROM deltalake_db").show()
---
+------------+---------+-----------+
| namespace|tableName|isTemporary|
+------------+---------+-----------+
|deltalake_db| trainer| false|
+------------+---------+-----------+
3️⃣ Create delta type table
csvSince data from an existing filedeltacannot be inserted directly into a table of the same type simultaneously with its creation,deltayou must create the table through two steps as follows.deltaCreate empty table of typedeltacsvInsert table data into the table
▪ 1) Create table
trainer_deltadeltaCreates a table named ./workspace/spark/deltalake/delta_local/trainer_delta/deltaWe have configured the settings so that table-related data is stored under the corresponding path .
query = f"""
CREATE TABLE IF NOT EXISTS deltalake_db.trainer_delta (
  id INT,
  name STRING,
  age INT,
  hometown STRING,
  prefer_type STRING,
  badge_count INT,
  level STRING
)
USING delta
LOCATION '/workspace/spark/deltalake/delta_local/trainer_delta/'
"""
spark.sql(query)
▪ 2) Insert data
- Insert
trainerthe data from the table created above into the table.trainer_delta
query = """
INSERT INTO deltalake_db.trainer_delta
SELECT * FROM deltalake_db.trainer;
"""
spark.sql(query)- Once data insertion is complete,
_delta_log/you can verify that a new folder and parquet file have been created in the delta table directory.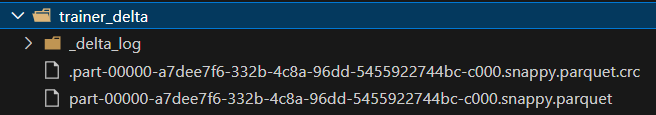
4️⃣ Reading delta type tables
- In PySpark, you can read tables stored in slightly different ways.
▪ 1) Basic reading in Spark
LOCAL_DELTA_PATH = '/workspace/spark/deltalake/delta_local/trainer_delta'df = spark.read.format("delta").load(LOCAL_DELTA_PATH)
df.show(5)
---
+---+------+---+--------+-----------+-----------+------------+
| id| name|age|hometown|prefer_type|badge_count| level|
+---+------+---+--------+-----------+-----------+------------+
| 1| Brian| 28| Seoul| Electric| 8| Master|
| 3| Susan| 18| Gwangju| Rock| 7| Expert|
| 6| Vicki| 17| Daejeon| Ice| 4|Intermediate|
| 9|Olivia| 45| Incheon| Psychic| 3|Intermediate|
| 10| Mark| 16| Gangwon| Fire| 4|Intermediate|
+---+------+---+--------+-----------+-----------+------------+
only showing top 5 rows
delta.Read as ▪ 2)
query = f"SELECT * FROM delta.`{LOCAL_DELTA_PATH}`"
spark.sql(query)
▪ 3) Read from Hive Catalog
spark.table('deltalake_db.trainer_delta')5️⃣ Save after editing the table
- This time, we will modify the table contents and overwrite the existing directory. This step is intended to prepare for future table change history inquiries and to practice Time Travel queries, a core feature of Delta Lake.
▪ 1) Save after excluding 'Beginner'
# Beginner 제외한 dataframe 생성 df_1 = df.filter(F.col('level') != 'Beginner')# 기존 경로에 덮어쓰기
df_1.write \
.format('delta') \
.mode('overwrite') \
.save(LOCAL_DELTA_PATH)# 데이터 확인
df = spark.read.format("delta").load(LOCAL_DELTA_PATH)
df.select('level').distinct().show()
---
+------------+
| level|
+------------+
| Expert|
| Advanced|
| Master|
|Intermediate|
+------------+
▪ 2) Save after excluding 'Advanced'
# Advanced 제외한 dataframe 생성 df_2 = df_1.filter(F.col('level') != 'Advanced')# 기존 경로에 덮어쓰기
df_2.write \
.format('delta') \
.mode('overwrite') \
.save(LOCAL_DELTA_PATH)# 데이터 확인
df = spark.read.format("delta").load(LOCAL_DELTA_PATH)
df.select('level').distinct().show()
---
+------------+
| level|
+------------+
| Expert|
| Master|
|Intermediate|
+------------+
- You can see that as the data is overwritten, a parquet file is added, and
_delta_log/metadata (files) are also added within the folder ..json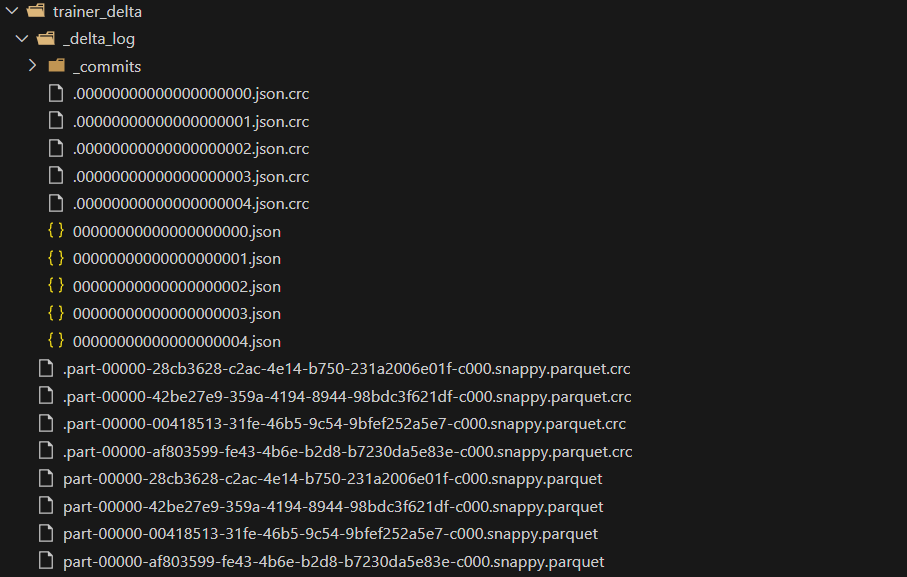
6️⃣ Change History Lookup and Time Travel Query
▪ 1) View History
deltaView the change history for the table.- So far, the table has a structure where a total of three write operations have occurred since the initial creation (CREATE). Therefore, the versions also exist as 0, 1, 2, and 3.
- VERSION 0 →
trainer_deltaTable creation status, No data - VERSION 1 →
trainerInitial state after data is inserted into the table - VERSION 2 → Saved state after excluding 'Beginner' rows
- VERSION 3 → Saved state after excluding 'Advanced' row
- VERSION 0 →
query = "DESCRIBE HISTORY deltalake_db.trainer_delta"spark.sql(query).show(vertical=True, truncate=False)
---
-RECORD 0--------------------------------------------------------------------------------------------------------------
version | 3
timestamp | 2025-03-21 02:09:39.085
userId | NULL
userName | NULL
operation | WRITE
operationParameters | {mode -> Overwrite, partitionBy -> []}
job | NULL
notebook | NULL
clusterId | NULL
readVersion | 2
isolationLevel | Serializable
isBlindAppend | false
operationMetrics | {numFiles -> 1, numOutputRows -> 42, numOutputBytes -> 3125}
userMetadata | NULL
engineInfo | Apache-Spark/3.5.1 Delta-Lake/3.2.0
-RECORD 1--------------------------------------------------------------------------------------------------------------
version | 2
timestamp | 2025-03-21 02:08:32.646
userId | NULL
userName | NULL
operation | WRITE
operationParameters | {mode -> Overwrite, partitionBy -> []}
job | NULL
notebook | NULL
clusterId | NULL
readVersion | 1
isolationLevel | Serializable
isBlindAppend | false
operationMetrics | {numFiles -> 1, numOutputRows -> 85, numOutputBytes -> 3868}
userMetadata | NULL
engineInfo | Apache-Spark/3.5.1 Delta-Lake/3.2.0
-RECORD 2-------------------------------------------------------------------------------------------------------------
version | 1
timestamp | 2025-03-21 01:46:21.446
userId | NULL
userName | NULL
operation | WRITE
operationParameters | {mode -> Append, partitionBy -> []}
job | NULL
notebook | NULL
clusterId | NULL
readVersion | 0
isolationLevel | Serializable
isBlindAppend | true
operationMetrics | {numFiles -> 1, numOutputRows -> 90, numOutputBytes -> 3980}
userMetadata | NULL
engineInfo | Apache-Spark/3.5.1 Delta-Lake/3.2.0
-RECORD 3--------------------------------------------------------------------------------------------------------------
version | 0
timestamp | 2025-03-21 01:43:25.471
userId | NULL
userName | NULL
operation | CREATE TABLE
operationParameters | {partitionBy -> [], clusterBy -> [], description -> NULL, isManaged -> false, properties -> {}}
job | NULL
notebook | NULL
clusterId | NULL
readVersion | NULL
isolationLevel | Serializable
isBlindAppend | true
operationMetrics | {}
userMetadata | NULL
engineInfo | Apache-Spark/3.5.1 Delta-Lake/3.2.0
▪ 2) Time Travel - Version
- Whenever the table is modified, the contents of the table corresponding to a specific version are retrieved based on the assigned version number.
👉 Load initial version (version 0) table
df_pre = spark.read \
    .format("delta") \
    .option("versionAsof", 0) \
    .load(LOCAL_DELTA_PATH)

df_pre.select('level').distinct().show()
---

+-----+

|level|

+-----+

+-----+
👉 Load version 2 table
df_pre = spark.read \
    .format("delta") \
    .option("versionAsof", 2) \
    .load(LOCAL_DELTA_PATH)

df_pre.select('level').distinct().show()
---

+------------+

|       level|

+------------+

|      Expert|

|    Advanced|

|      Master|

|Intermediate|

+------------+
👉 Querying Time Travel with SQL
df_pre = spark.sql("SELECT * FROM deltalake_db.trainer_delta VERSION AS OF 3")
df_pre.select('level').distinct().show()

---

+------------+

|       level|

+------------+

|      Expert|

|      Master|

|Intermediate|

+------------+
▪ 3) Time Travel - Timestamp
- This is a query method based on table modification time, retrieving the status (version) of the Delta table that existed at a specified time (TIMESTAMP).
👉 Load table status for a specified time period
TABLE_TIMESTAMP = "2025-03-21T02:09:00"
spark.read.format("delta") \

.option("timestampAsOf", TABLE_TIMESTAMP) \

.table("deltalake_db.trainer_delta")
👉 Retrieving tables for a specific time zone using SQL
TABLE_TIMESTAMP = "2025-03-21T02:09:00"
spark.sql(f"SELECT * FROM deltALake_db.trainer_delta TIMESTAMP AS OF '{TABLE_TIMESTAMP}'")
7️⃣ Schema Change Task
- Delta Lake uses the 'Strict Schema Enforcement' option, which causes an error if you attempt to write data that differs from the existing table schema. Therefore, if the schema of an existing table changes, you must add specific options to enable overwriting.
- The details of the practical training are as follows.
- 기존 컬럼 : ['id', 'name', 'age', 'hometown', 'prefer_type', 'badge_count', 'level']
- 변경된 테이블 컬럼 : ['id', 'name', 'age', 'hometown', 'prefer_type', 'badge_count', 'level', 'dummy_col']
👉 'dummy_col' 이라는 컬럼이 추가되어 스키마가 변경된 테이블 덮어쓰기
▪ 1) Standard write - Operation failed
LOCAL_DELTA_PATH = '/workspace/spark/deltalake/delta_local/trainer_delta'# 테이블 불러오기
df = spark.table("deltalake_db.trainer_delta")# 'dummy_col' 컬럼 추가
df_diff = df.withColumn('dummy_col', F.lit(1))# 스키마 합치기 시도
df_diff.write \
.format('delta') \
.mode('overwrite') \
.save(LOCAL_DELTA_PATH)# 덮어쓰려는 테이블의 스키마가 달라 아래의 에러 발생
# 👇👇👇👇👇
---
AnalysisException: [_LEGACY_ERROR_TEMP_DELTA_0007] A schema mismatch detected when writing to the Delta table (Table ID: 31dbae5e-d042-467b-9454-e483fdad97bb).
To enable schema migration using DataFrameWriter or DataStreamWriter, please set:
'.option("mergeSchema", "true")'.
For other operations, set the session configuration
spark.databricks.delta.schema.autoMerge.enabled to "true". See the documentation
specific to the operation for details.Table schema:
root
-- id: integer (nullable = true)
-- name: string (nullable = true)
-- age: integer (nullable = true)
-- hometown: string (nullable = true)
-- prefer_type: string (nullable = true)
-- badge_count: integer (nullable = true)
-- level: string (nullable = true)Data schema:
root
-- id: integer (nullable = true)
-- name: string (nullable = true)
-- age: integer (nullable = true)
-- hometown: string (nullable = true)
-- prefer_type: string (nullable = true)
-- badge_count: integer (nullable = true)
-- level: string (nullable = true)
-- dummy_col: integer (nullable = true)To overwrite your schema or change partitioning, please set:
'.option("overwriteSchema", "true")'.
Note that the schema can't be overwritten when using
'replaceWhere'.
▪ 2) Use with the schema merging option
- To overwrite a table with a different schema,
option("mergeSchema", "true")you must add options.
df_diff.write \
    .format('delta') \
    .mode('overwrite') \
    .option("mergeSchema", "true") \
    .save(LOCAL_DELTA_PATH)
8️⃣ Optimize file status
-
https://docs.databricks.com/aws/en/sql/language-manual/delta-optimize
-
Since Delta tables are fundamentally structured as continuously loaded files, a large number of small files accumulate over time. This leads to degraded query performance and increased read overhead. In this case, performance can be improved by merging data into a larger file using OPTIMIZE.
Optimization method explanation Basic Optimize Merging small files improves read performance Z-Ordering Sort by frequently filtered columns → Reduce scans and improve query performance Partition-based Optimize Selective optimization of only frequently accessed partitions, such as specific dates/regions
▪ 1) Standard Optimization
- It applies the standard optimization method that Delta Lake performs by default.
query = "OPTIMIZE deltalake_db.trainer_delta"
spark.sql(query)
▪ 2) Z-Ordering Optimization
- A function that optimizes the physical storage order of data based on specific columns.
- Applying Z-Order based on frequently filtered columns can reduce unnecessary file scans during queries.
query = """
OPTIMIZE deltalake_db.trainer_delta
ZORDER BY (trainer_id, region)
"""
spark.sql(query)
<▪ 3) Partition Optimization
- Instead of optimizing for the entire table, it merges only a specific range of partitioned data.
query = """
OPTIMIZE deltalake_db.trainer_delta
WHERE level = 'Master'
"""
spark.sql(query)
9️⃣ Delete past data (VACUUM)
- https://docs.databricks.com/aws/en/sql/language-manual/delta-vacuum
- In Delta Lake, past parquet files remain even if data is modified or deleted.
- Since it is wasteful to keep past versions of files that are no longer used, you can use the VACUUM function to delete data older than a specific period.
deltaFor data of a specific type, historical file data should not be deleted directly from the directory but must be deletedVACUUMvia a command to avoid compromising table consistency and ensure smooth future operations.VACUUMWhen the operation occurs, it becomes impossible to Time Travel to a date prior to the deleted date to retrieve data.- The default retention period for files is 168 hours (7 days), and you can adjust the retention period by modifying the spark config.
▪ 1) Disable default retention period
- You must disable the default settings in Spark to manage the retention period customly.
# 설정 확인
spark.conf.get("spark.databricks.delta.retentionDurationCheck.enabled")
-> 'true'
# 유지 기간 설정 해제

spark.conf.set("spark.databricks.delta.retentionDurationCheck.enabled", "false")
▪ 2) Execute the VACUUM command
VACUUMExecute the command to delete parquet files created before the user-specified period .DRY RUNThe option is a setting that prevents the operation from actually happening.
# 기본 VACUUM 명령 (168시간 이전의 파일 삭제) spark.sql("VACUUM deltalake_db.trainer_delta").show(truncate=False)# 현재 버전 이전의 파일들 삭제
spark.sql("VACUUM deltalake_db.trainer_delta RETAIN 0 HOURS DRY RUN").show(truncate=False)
# 2일 이전의 파일들 삭제
spark.sql("VACUUM deltalake_db.trainer_delta RETAIN 2 DAYS DRY RUN").show(truncate=False)
▪ 3) Set retention period when creating table
deltaSets the default retention period when creating a type table.
query = f"""
CREATE TABLE IF NOT EXISTS deltalake_db.trainer_delta_2 (
  id INT,
  name STRING,
  age INT,
  hometown STRING,
  prefer_type STRING,
  badge_count INT,
  level STRING
)
USING delta
LOCATION '/workspace/spark/deltalake/delta_local/trainer_delta_2/'
TBLPROPERTIES ('delta.deletedFileRetentionDuration' = 'interval 2 days');
"""
spark.sql(query)
🔟 Parquet to Delta Conversion
- https://docs.databricks.com/aws/en/sql/language-manual/delta-convert-to-delta
parquetdeltaThis is a function that converts data stored in a specific format into table data of a specific type.
▪ 1) General Parquet Data Conversion
👉 fish_data.csvSaves data as parquet.
# csv 파일 읽어오기
fish = spark.read.option('header', 'true').csv('fish_data.csv')
# 로컬 디렉토리 저장 + Catalog 저장

fish.write \

.mode('overwrite') \

.format('parquet') \

.option('path', '/workspace/spark/deltalake/delta_local/fish_parquet/') \

.saveAsTable('deltalake_db.fish_parquet')
Convert parquetdata stored as 👉 todelta
query = """
CONVERT TO DELTA
parquet.`/workspace/spark/deltalake/delta_local/fish_parquet/`
"""
spark.sql(query)
▪ 2) Converting partitioned parquet data
👉 SpeciesWrite column-partitioned Parquet data
fish_df.write.mode('overwrite')\
    .format('parquet') \
    .partitionBy('Species') \
    .option('path', '/workspace/spark/deltalake/delta_local/fish_parquet_partitioned/') \
    .saveAsTable('deltalake_db.fish_parquet_partitioned')
delta👉 Convert partitioned parquet data to
query = """
CONVERT TO DELTA
parquet.`/workspace/spark/deltalake/delta_local/fish_parquet_partitioned/`
PARTITIONED BY (Species STRING)
"""
spark.sql(query)
Reference materials
- Delta Lake Documentation
- Delta Lake Quickstart - Apache Spark
- 𝑫𝒆𝒍𝒕𝒂 𝑳𝒂𝒌𝒆 𝒊𝒏 𝑨𝑾𝑺 - 𝑭𝒓𝒐𝒎 𝒁𝒆𝒓𝒐 𝒕𝒐 𝑯𝒆𝒓𝒐 𝒊𝒏 4 𝒉𝒐𝒖𝒓𝒔