Summary
- The test loss of a language model follows a power law with respect to each of model size , dataset size , and training compute , when the other two are not the bottleneck. In contrast, architecture shape such as depth, width, and the number of heads has almost no effect on loss as long as the non-embedding parameter count is the same.
- When and are scaled together, the degree of overfitting is determined by a single ratio, . In other words, if the model is made 8 times larger, the data only needs to be increased by about 5 times.
- Under a fixed compute budget, the optimal strategy is to make the model much larger () and stop training well before convergence.
1. Introduction
The performance of language modeling depends on the model architecture, the number of parameters, the amount of compute, the amount of available data, and so on. This paper targets Transformer language modeling and experimentally measures which of these factors are the main ones that actually determine performance. According to the results of several experiments conducted under varying conditions, performance scales as a power law with respect to training time, context length, dataset size, model size, and compute budget.
Since the paper compares results across many conditions, it defines and uses several notations.
: Cross-entropy loss
: Number of model parameters
: Dataset size
: Total non-embedding training compute
: Estimate of minimum amount of non-embedding compute to reach a given loss
2. Background & Methods
2.1. Parameter and Compute Scaling of Transformers
The hyperparameters of the Transformer architecture are set as follows.
- : number of layers
- : dimension of the residual stream
- : intermediate dimension of the feed-forward layer
- : dimension of the attention output
- : number of attention heads per layer
① Model size
A single layer consists of the following parameters.
- Q, K, V projections and output projection of attention:
- Two linear layers of the FFN:
Therefore, the total number of parameters excluding embeddings and biases is
② Compute
The amount of computation (FLOPs) for the forward pass of a single token is
Here, the second term is a context-length-dependent term arising from the attention score computation, and when it becomes much smaller than , so it can be ignored. In addition, since the compute of the backward pass is about twice that of the forward pass, the total training compute per token can be approximated as follows.
3. Empirical Results and Basic Power Laws
3.1. Transformer Shape and Hyperparameter Independence
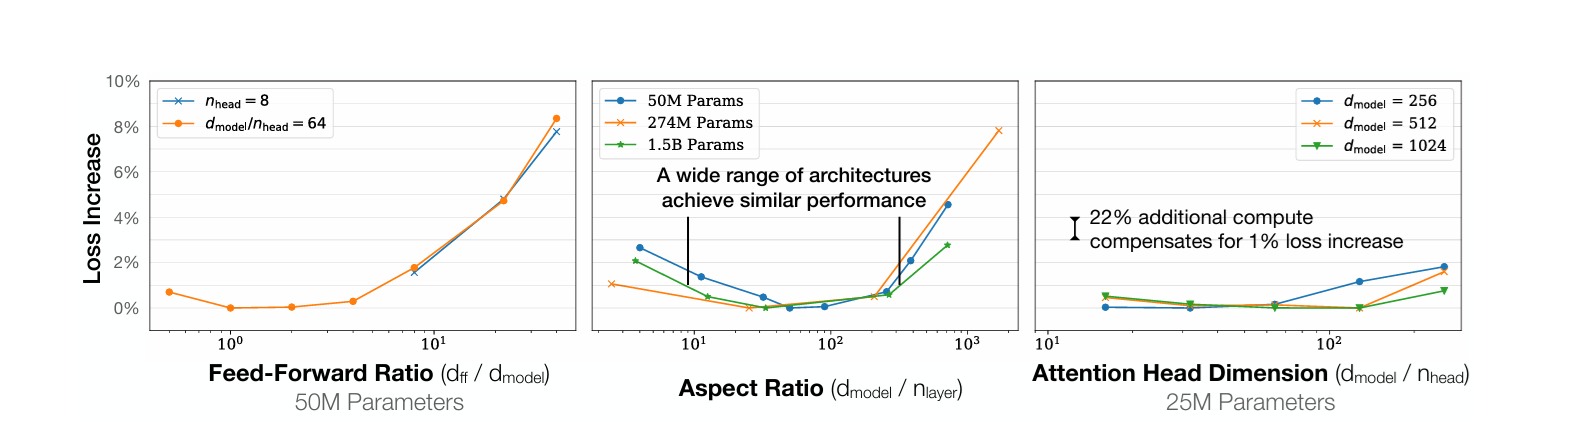
To check the effect of the Transformer's shape on performance, the loss was measured while fixing the non-embedding parameter count and changing one of , , and at a time. The resulting loss is as follows.
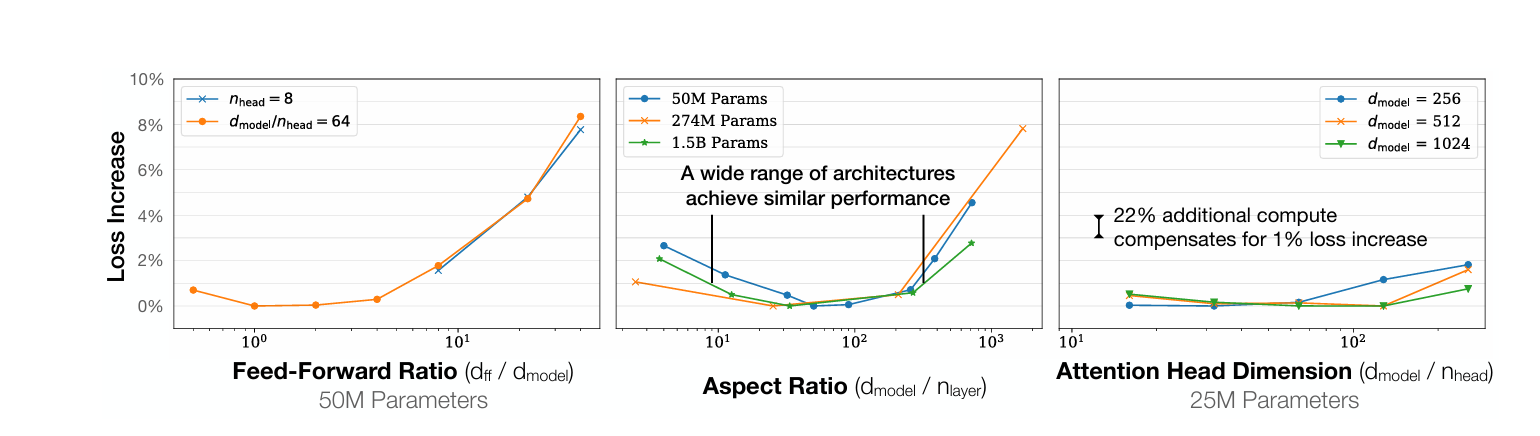
- Even when the feed-forward ratio, aspect ratio (), and head dimension are varied over a wide range, the change in loss stays within a few percent, and even architectures whose aspect ratios differ by a factor of 40 achieve similar performance.
- In other words, once is fixed, the performance of the Transformer does not depend much on its shape.
3.2. Performance with Non-Embedding Parameter Count
The value used to represent the size of a model is the number of parameters in the model. Here, parameters can be viewed from two main perspectives, depending on whether only the parameters trained for the actual objective function are counted, or whether embedding parameters are also included. Therefore, to express the relationship between parameter count and model performance more accurately, it must be decided which of the two values to use as the parameter count, and the following experiment was conducted as the verification process.
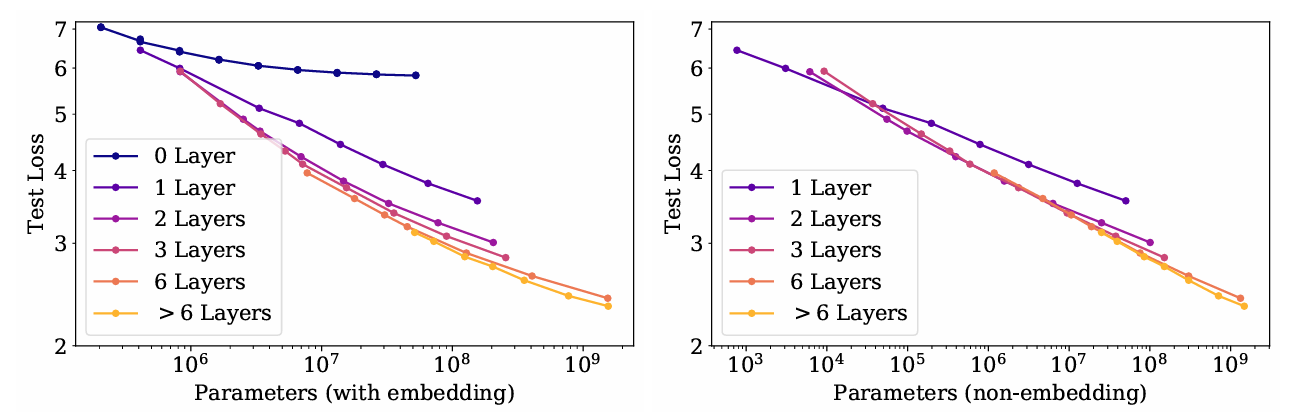
- Left: When embedding parameters are included in the count, the loss appears to depend not only on the number of parameters but also on .
- Right: When embedding parameters are excluded from the count, models with different depths converge onto a single line (power law). Only models with just one layer or with extreme depth/width ratios were exceptions.
The reason it looks like the left plot is that the smaller the model, the larger the share of embedding in the total parameters. The parameter count looks large, but the part actually used for computation is small, so the loss comes out poor. For this reason, the paper uses the non-embedding parameter count as in all subsequent analyses.
With this definition, the loss can be written as a function of .
3.3. Performance with Dataset Size and Compute
Dataset size
To make the amount of data the bottleneck of the model, a large model (, ) is trained on subsets of WebText2, and the lowest loss reachable with a given amount of data is measured. To compare the lowest losses, training is stopped once the test loss no longer decreases. The resulting relationship between loss and dataset size is as follows.
Compute
The training compute is . With fixed, is varied to find the model that achieves the lowest loss within that compute. Connecting these optimal points gives the following relationship.
The values written as in each equation are obtained through fitting to express the relationship on a log-log graph. The relationships of loss with respect to parameters, dataset, and compute are summarized as follows.
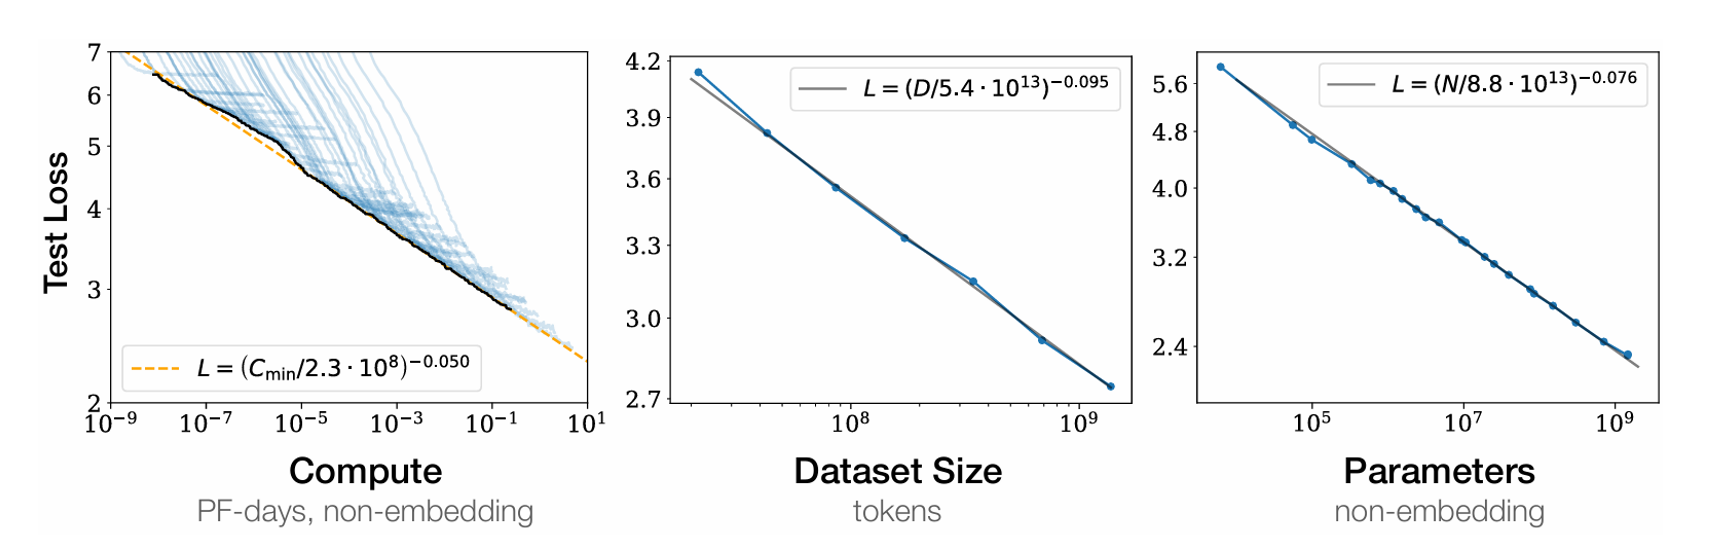
All three graphs are linear on log-log axes. The light blue curves in the left graph are the learning curves of models of different sizes, and their lower envelope (black line) forms the power law with respect to compute, . However, this power law holds only when the other two factors are not the bottleneck.
4. Charting the Infinite Data Limit and Overfitting
Up to this point, only one variable was made the bottleneck at a time in order to check the independent effect of each variable. This section deals with how the loss behaves when the two values and are changed simultaneously, and in particular with the overfitting that occurs when data is insufficient.
4.1. Proposed Equation
This loss as a function of and was chosen to satisfy the following principles.
Rescaling: If the vocabulary size or tokenization changes, the overall loss is expected to change by a constant factor, so the equation should naturally allow for such rescaling.
A limit imposed by the other variable even when one variable grows infinitely: If is fixed and , the loss should converge to , and if is fixed and , it should converge to .
is analytic at : It should be expandable as a series in integer powers of .
4.2. Results
Training was performed while varying and , stopped once the test loss no longer decreased, and then the parameters of the above equation were fitted.
| Parameter | ||||
|---|---|---|---|---|
| Value | 0.076 | 0.103 |
Overfitting
How much is lost compared to the loss with infinite data, , is defined as .
- The larger is, the more severe the overfitting.
- From the equation, depends only on .
- Since the variation in loss due to the random seed is about 0.02, there is considered to be no overfitting when . The condition that satisfies this is
In other words, when increasing model size, overfitting can be avoided by increasing data only sub-linearly. In this way, not only can the loss equation be fitted with data and parameters , but the relationship between and needed to prevent overfitting can also be identified.
5. Scaling Laws with Model Size and Training Time
Now, the number of training steps is also taken into account, and the loss as a function of and training time is combined into a single equation. Before that, the critical batch size is introduced to correct for the step count and compute that vary with batch size.
5.1 Critical Batch Size
Training time (number of steps) and compute vary with batch size .
- : Increasing the batch reduces the number of steps almost proportionally. Compute efficiency is good.
- : Increasing the batch further barely reduces the number of steps. The number of steps is close to the minimum, but compute is wasted.
The number of steps needed to reach a target loss and the amount of data processed have the following relationship. Here, is the number of tokens actually processed, which differs from the dataset size .
- : minimum number of steps needed to reach the target loss (when )
- : minimum amount of data needed to reach the target loss (when )
The critical batch size is defined as the ratio of the two.
- Since and are determined by the target loss, is also a function of the loss.
- Training with gives and , which is the balance point between time and compute.
Empirically, depends only on the loss, independent of model size, and follows the power law below.
The critical batch size measured as a function of loss is shown below.
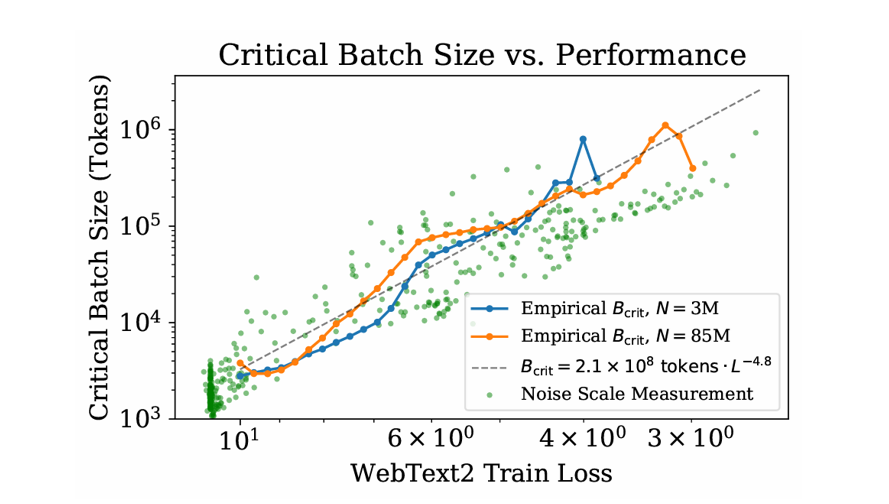
Every time the loss decreases by 13%, roughly doubles. Using this, the results (, ) of training with an arbitrary batch size can be converted into the minimum number of steps when and the minimum compute when .
5.2. Performance with Model size and Compute
Using , the loss can be written as a function of and training steps.
The first term is the limit set by model size when trained infinitely, and the second term is the loss caused by insufficient training.
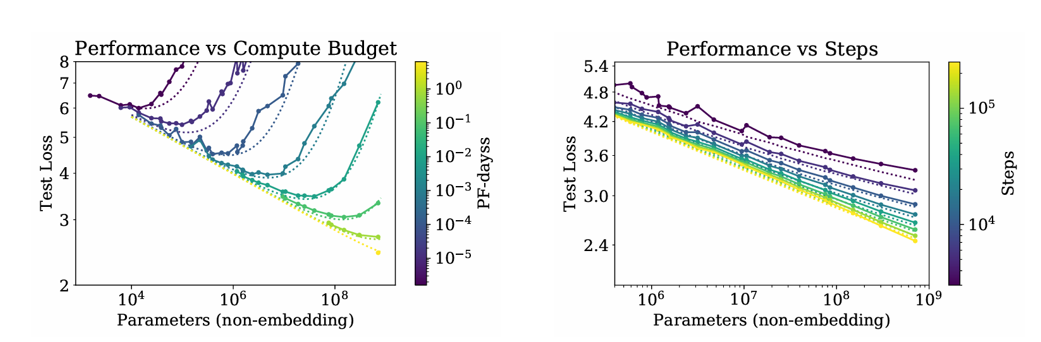
- Left: When compute is fixed, there exists an optimal model size that minimizes the loss. A model that is too small lacks capacity, and a model that is too large cannot be trained sufficiently with the same compute.
- Right: When the number of steps is fixed, the larger the model, the lower the loss.
- The dotted lines are the equation, which fits the experimental values well except early in training (small ).
5.3. Lower bound on Early Stopping Step
The learning curves for finite and infinite data are nearly identical up to around . Therefore, the lower bound on the number of steps at which training must be stopped due to overfitting can be estimated as follows.
The smaller the loss gap caused by insufficient data, , the longer training can continue before overfitting begins.
6. Optimal Allocation of the Compute Budget
6.1. Optimal Performance and Allocations
Using corrected with , the loss can be rewritten as a function of , . Then, finding the optimal model size that minimizes the loss for a given compute gives
Since and , the remaining number of steps is
In other words, the conclusion is as follows.
When scaling up a language model with an optimal allocation of compute, one should mainly increase the model size , increase the batch size along with , and barely increase the number of steps.
6.2 Predictions from
By combining the equation from Section 5.2 with the equation, the exponent of can be predicted theoretically.
This agrees well with the directly measured value of 0.050. This is evidence that the three independent power laws are consistent with one another.
6.3 Contradictions and a Conjecture
Continuing to apply these scaling laws leads to a contradiction.
- To avoid overfitting, data must grow as .
- However, the data actually seen when training compute-efficiently is
which grows much more slowly than the required rate. Therefore, even without reusing data, training will eventually enter the overfitting regime.
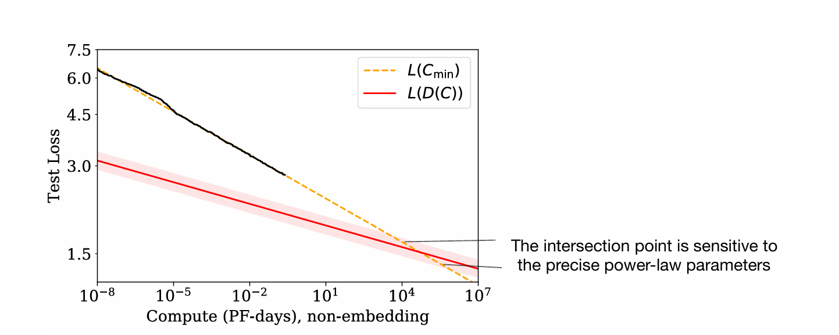
- (orange dotted line) decreases quickly as compute increases. To the left of the intersection, compute is the bottleneck, so increasing compute reduces the loss.
- (red line) is the lower bound on the loss achievable with the amount of data seen at that compute. This line decreases more slowly.
- To the right of the intersection, falls below , which would mean the loss drops below the limit possible with that data even though data is insufficient, which is impossible. Therefore, the scaling laws must break down before the intersection.
The intersection is at roughly PF-days, parameters, tokens, and nats/token. The paper conjectures that the loss at this point, , may be an estimate of the per-token entropy of natural language. However, since the location of the intersection is highly sensitive to the power-law exponents, it cannot be taken as an exact value.
7. Discussion
- The loss of a language model follows consistent power laws in (model size), (data), and (compute), and depends very little on architecture or hyperparameters.
- Large models are far more sample-efficient than previously thought. They need fewer steps and less data to reach the same loss. Therefore, given a fixed compute budget, it is more efficient to train a large model and stop before convergence than to train a small model until convergence.
8. My Take
1. What the loss at the intersection means
The loss at the intersection where the two power laws meet in the compute-data tradeoff corresponds, if the paper's conjecture is right, to the per-token entropy of natural language. If so, no matter how much model size or compute is increased, the loss cannot be pushed below this value. However, as the paper itself notes, this is a conjecture, and the location of the intersection is highly sensitive to the exponent values.
2. What if were defined as information content rather than token count?
Following this interpretation, I think what ultimately matters is the amount of information each token carries when the data is encoded. This paper simply defines dataset size as the number of tokens and expresses as a function of . If information content were defined as something like the total dimension of the encoded data and used in place of , I wonder whether a more accurate relationship could be obtained than when using the token count.
3. Which to scale: the model or the data
The LLaMA paper (based on the results of Chinchilla (Hoffmann et al., 2022)) holds that, for the same cost, training on more new data yields better performance than only increasing model size. In contrast, comparing the exponents in this paper, as compute increases, the optimal model size grows as while data grows only as , so the model grows much more than the data. It is interesting that the two papers reach nearly opposite conclusions on the same question.
References
- Kaplan, J., McCandlish, S., Henighan, T., Brown, T. B., Chess, B., Child, R., Gray, S., Radford, A., Wu, J., & Amodei, D. (2020). Scaling Laws for Neural Language Models. arXiv:2001.08361
- McCandlish, S., Kaplan, J., Amodei, D., & OpenAI Dota Team (2018). An Empirical Model of Large-Batch Training. arXiv:1812.06162
- Hoffmann, J. et al. (2022). Training Compute-Optimal Large Language Models. arXiv:2203.15556
- Touvron, H. et al. (2023). LLaMA: Open and Efficient Foundation Language Models. arXiv:2302.13971
This post was translated from the original Korean version with the help of AI, so some errors may remain.
