Pipeline
- Each task is called pipe stage or pipe segment
- Stage duration is called the processor cycle
- All stages must be able to proceed at the same time:
– It is determined by the slowest stage = the longest stage determines processor cycle time. - Goal of pipelining is to increase throughput – number of instructions completed per clock cycle
- Ideally this should lead to throughput of one instruction per clock cycle
- In ideally balanced pipeline with n stages:
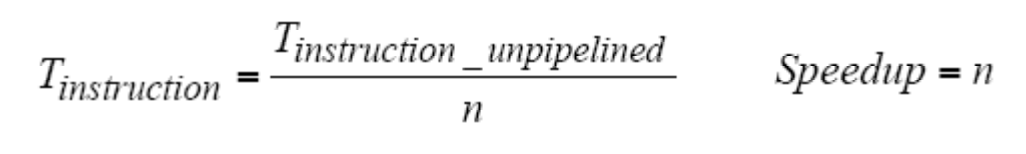
Pipeline Speedup
Pipelining increases throughput, reduces the average execution time per instruction
- It does not reduce the time needed to execute each instruction
- Frequently this time is slightly increased due to overhead involved in passing between stages
- A program runs faster, but no single instruction runs faster
Pipeline Hazards
완벽해 보이는 파이프라인의 발목을 잡는 3가지 장애물입니다. 이때 하드웨어는 파이프라인을 잠시 멈추는 Stall (또는 Bubble)을 발생시킵니다. 첨부하신 두 번째 이미지가 바로 이 Stall이 발생한 다이어그램입니다.
-
Structure Hazard (구조적 해저드): 하드웨어 자원이 부족해서 발생. (예: 메모리가 1개뿐인데, 1번 명령어가 MEM 단계에서 메모리를 쓰고 있으면 4번 명령어가 IF 단계에서 메모리를 읽지 못하고 기다려야 함)
-
Data Hazard (데이터 해저드): 앞의 명령어가 계산 중인 결과를 뒤의 명령어가 바로 가져다 써야 할 때 발생.
-
Control Hazard (제어 해저드): Branch 명령어 때문에 다음에 무얼 실행할지 몰라서 발생.
Performance Degradation Due to Hazards
IC, CCT는 같거나 비슷하다, 관건은 CPI이다.
(분자): 파이프라인 단계 수입니다.
(예: 5단계면 최고 속도 향상치는 5배입니다.)
(분모): 해저드 때문에 발생하는 페널티입니다.
예시: 5단계 파이프라인()에서 해저드 때문에 명령어 1개당 평균 0.5사이클씩 대기(Stall)해야 한다고 칩시다.즉, 원래 5배 빨라져야 할 파이프라인이 해저드 때문에 3.33배밖에 빨라지지 못한 것입니다.
Design Verification engineer