Computer Arch (Memory)
1.Performance
Response time (also called executiontime) \- How long it takes to do a taskThroughput \- Total work done per unit time \- e.g., tasks/transaction
2.Pipeline
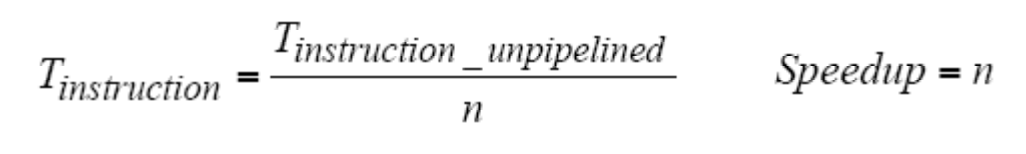
Each task is called pipe stage or pipe segmentStage duration is called the processor cycleAll stages must be able to proceed at the same time: – It is
3.Memory Hierarchy, CPU time
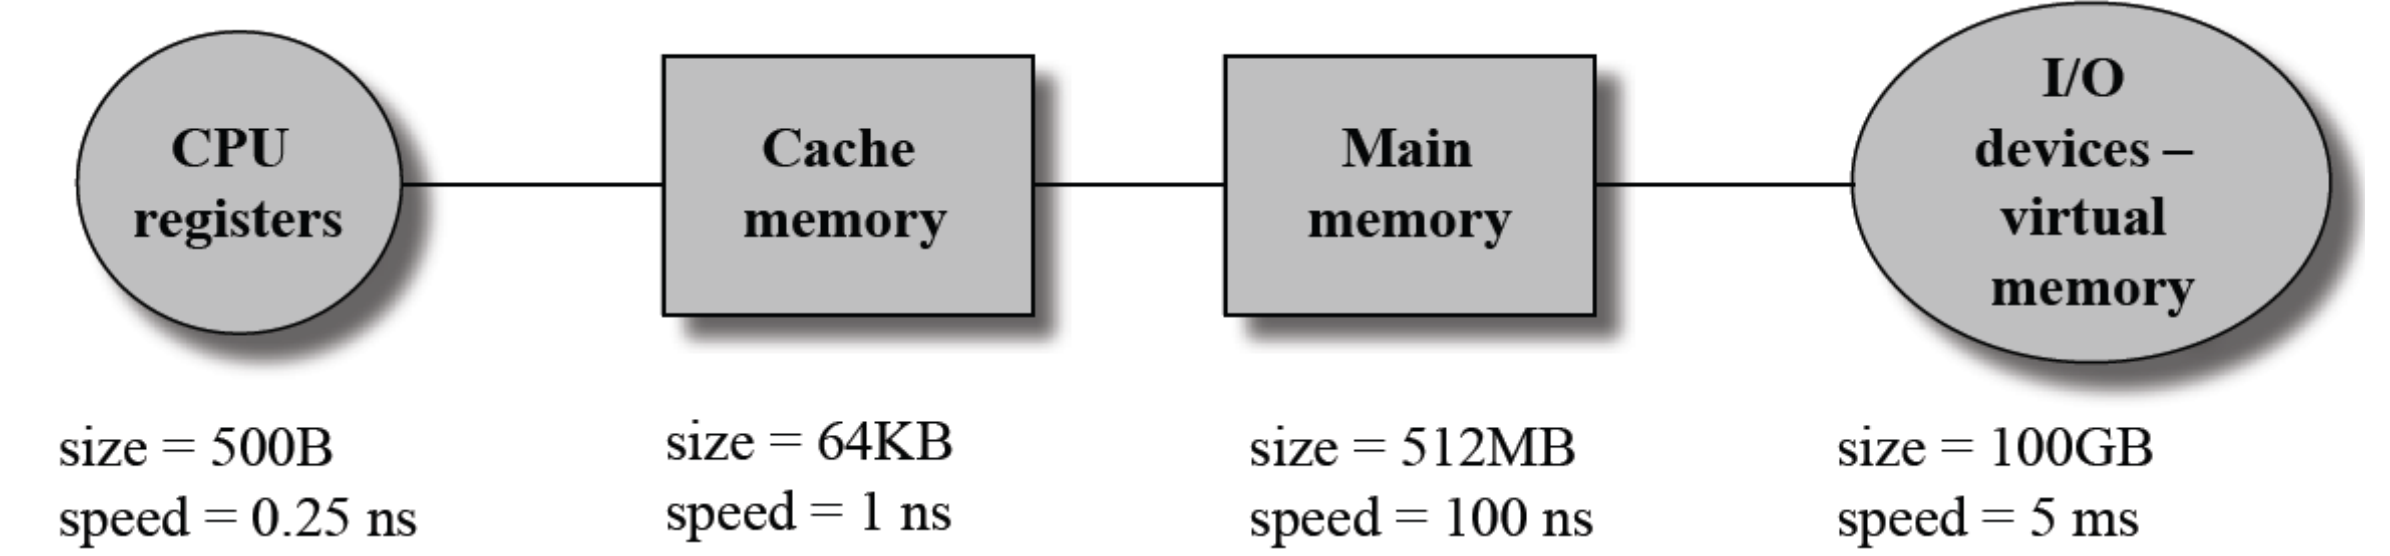
We would like to have a lot of fast memory, but smaller memory units are fasterFrequently application accesses to data exhibit spatial andtemporal loc
4.HW1
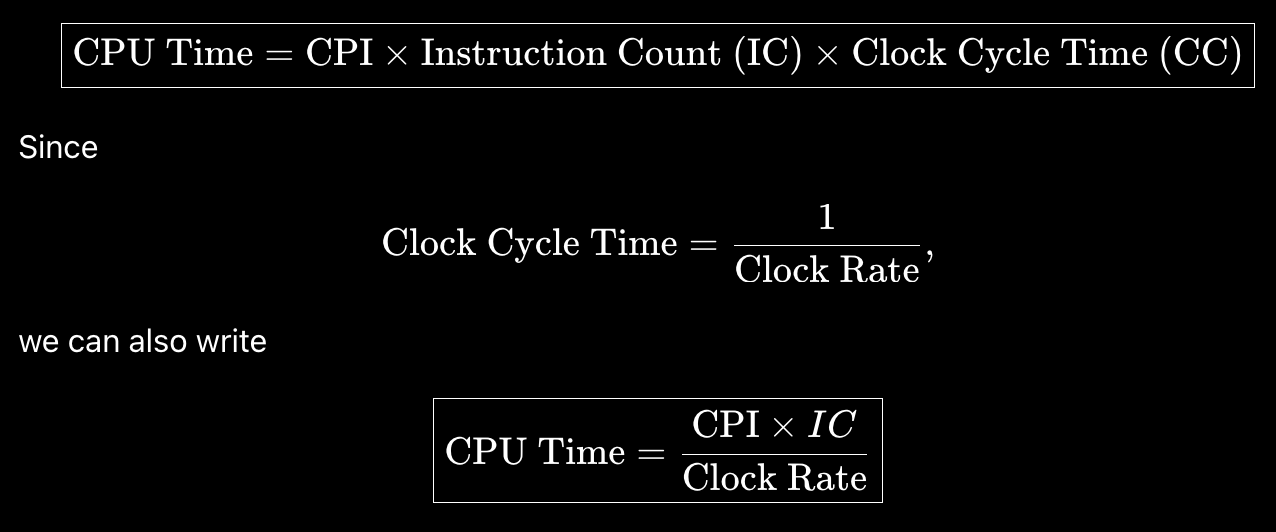
Consider two different implementations of the same instruction set architecture. The instructions can be divided into four classes according to their
5.Set Associative cache
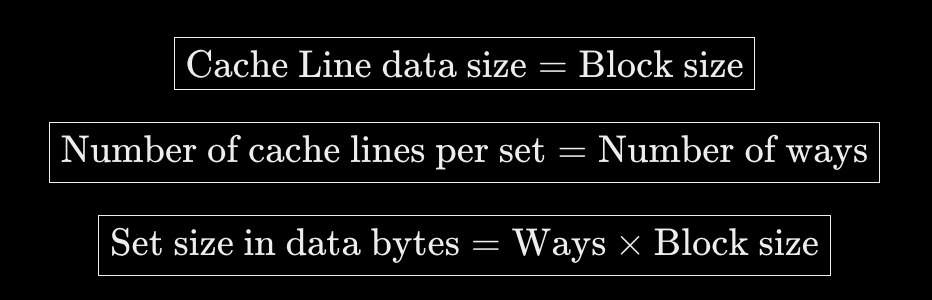
Q1: Where can a block be placed in the upper level?(Block placement)Q2: How is a block found if it is in the upper level?(Block identification)Q3: Whi
6.Write policy
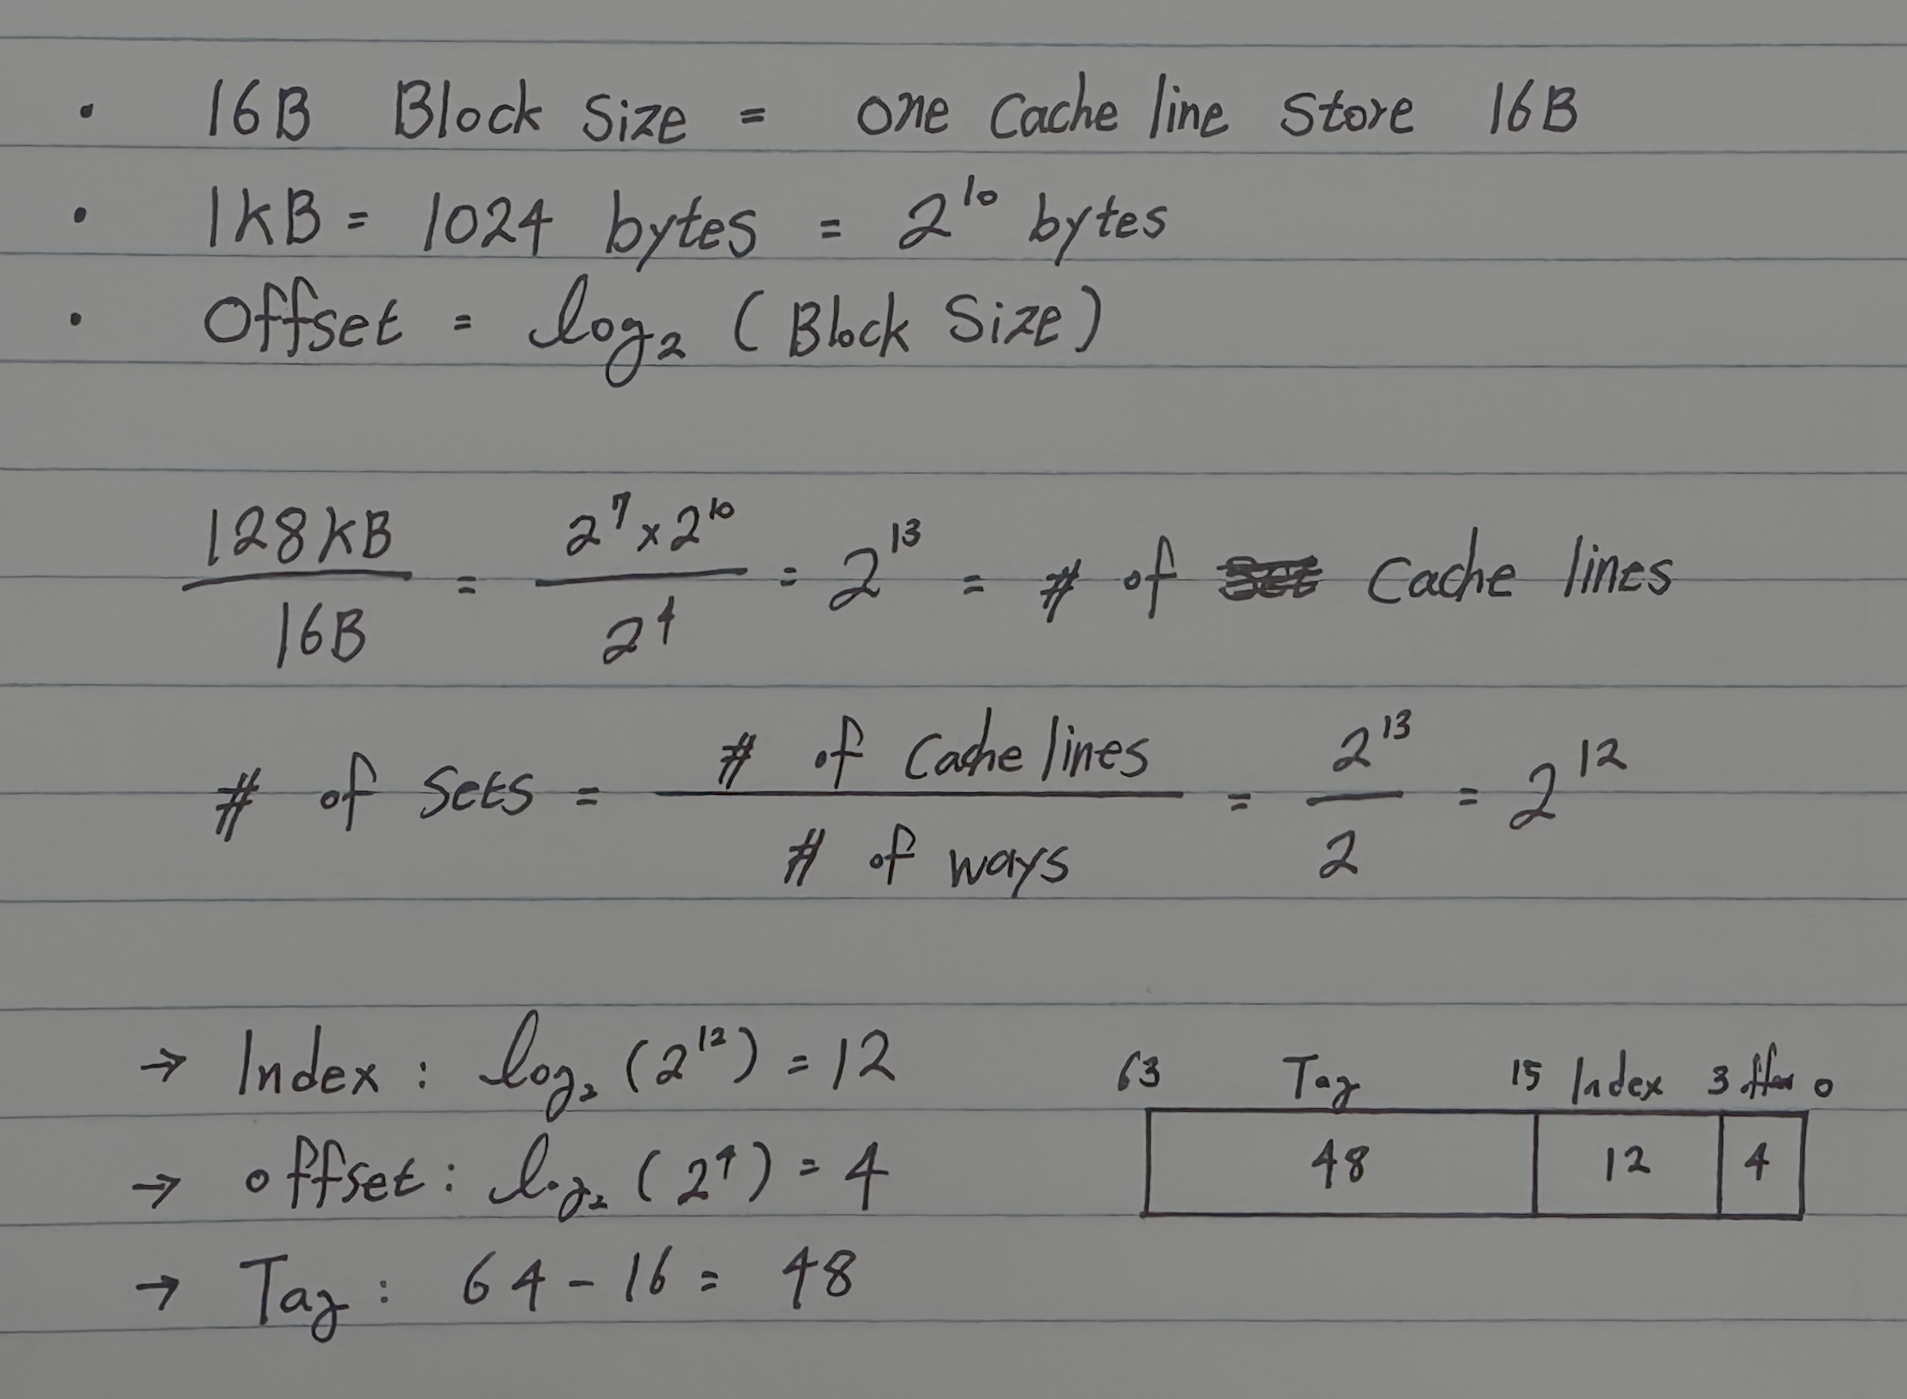
64-bit address, 2-way set associative, cache size 128KB (only for the data part), block size 16BSet-IndexTag ComparisonData TransferRead Hit time: 1 +
7.Memory Reference
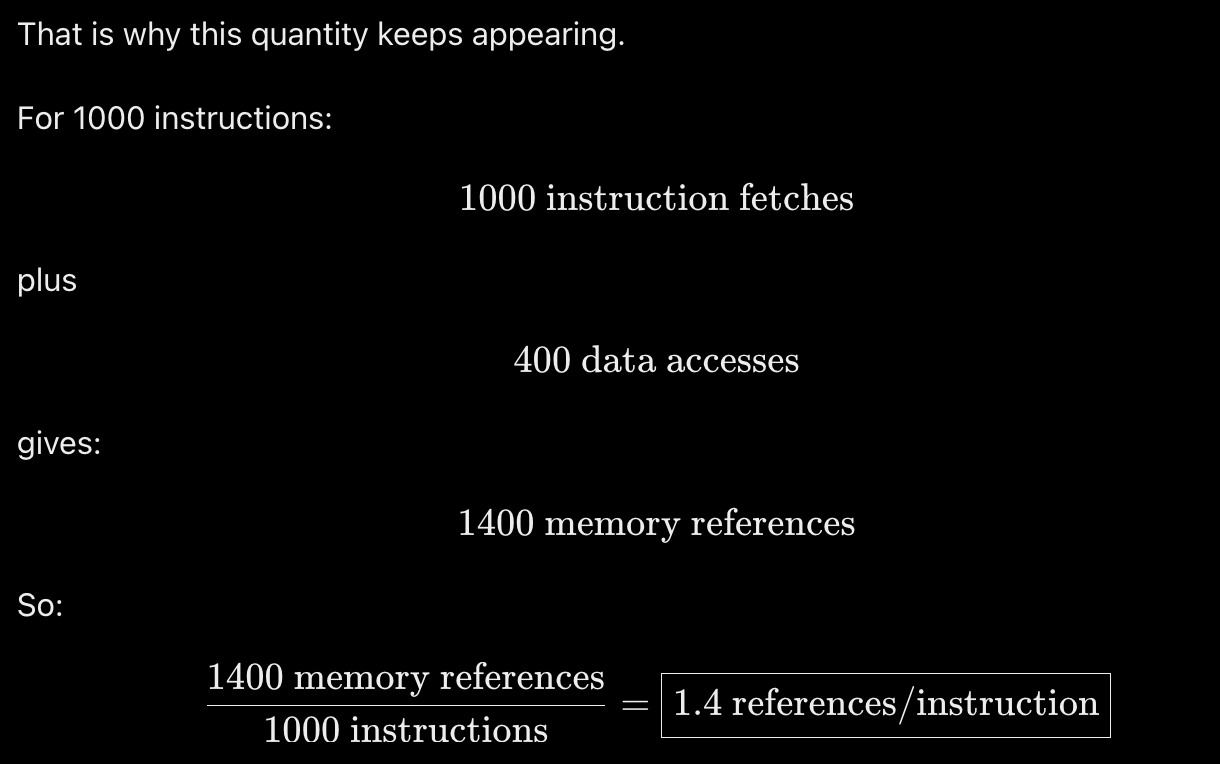
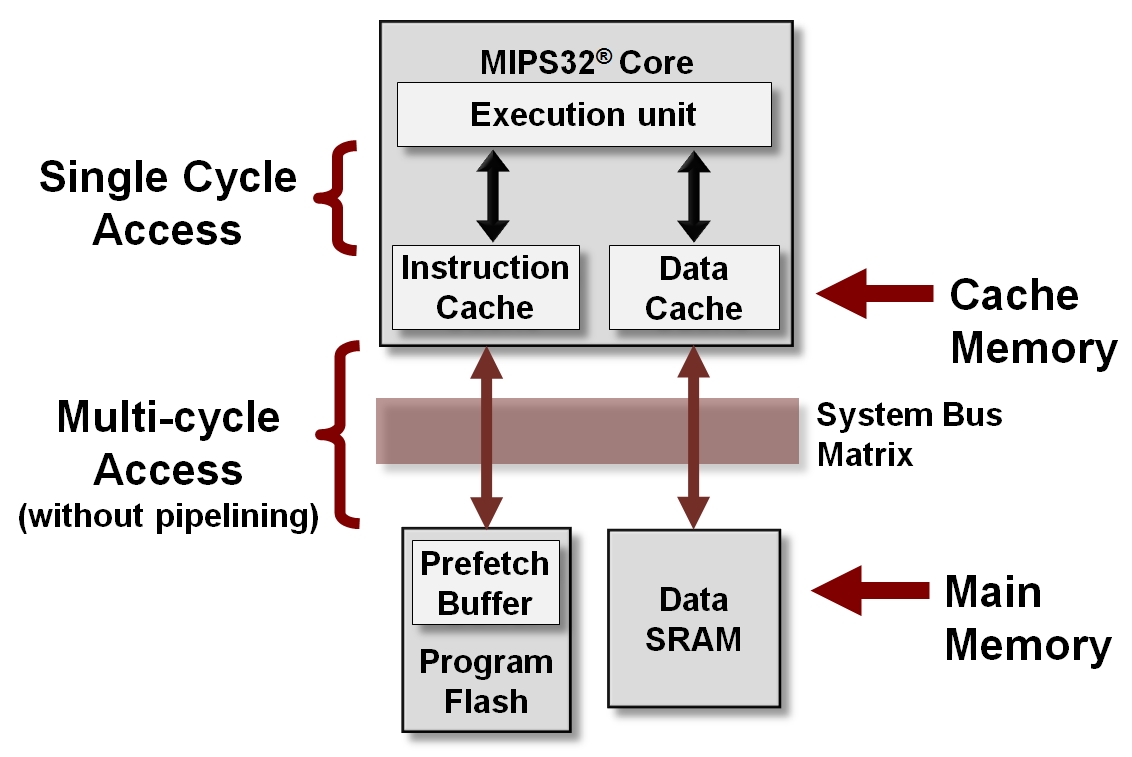
Memory Reference는 CPU가 메모리 계층(Cache / Memory)에 한 번 접근하는 것을 의미한다. 주로 두 종류가 있다.A memory reference means one access to the memory hierarchy/cache.In thes
8.Average Memory Access Time (AMAT)
Which has the lower miss rate: a 16KB instruction cache with a 16KB data cache or a unified 32KB cache? Use the following data for number of misses pe
9.Cache Optimizations

A. Reducing Miss Rate Miss categories (3C) Compulsory – first time when we want to access a block, cold-start misses. Capacity – if cache cannot hold all blocks needed in a program Conflict – if we ...
10.Multi-Level Cache
Reducing Miss Penalty Multi-Level Caches Victim Caches Multi-level Caches There is a trade-off between the size of the cache and the access time Sm
11.HW2
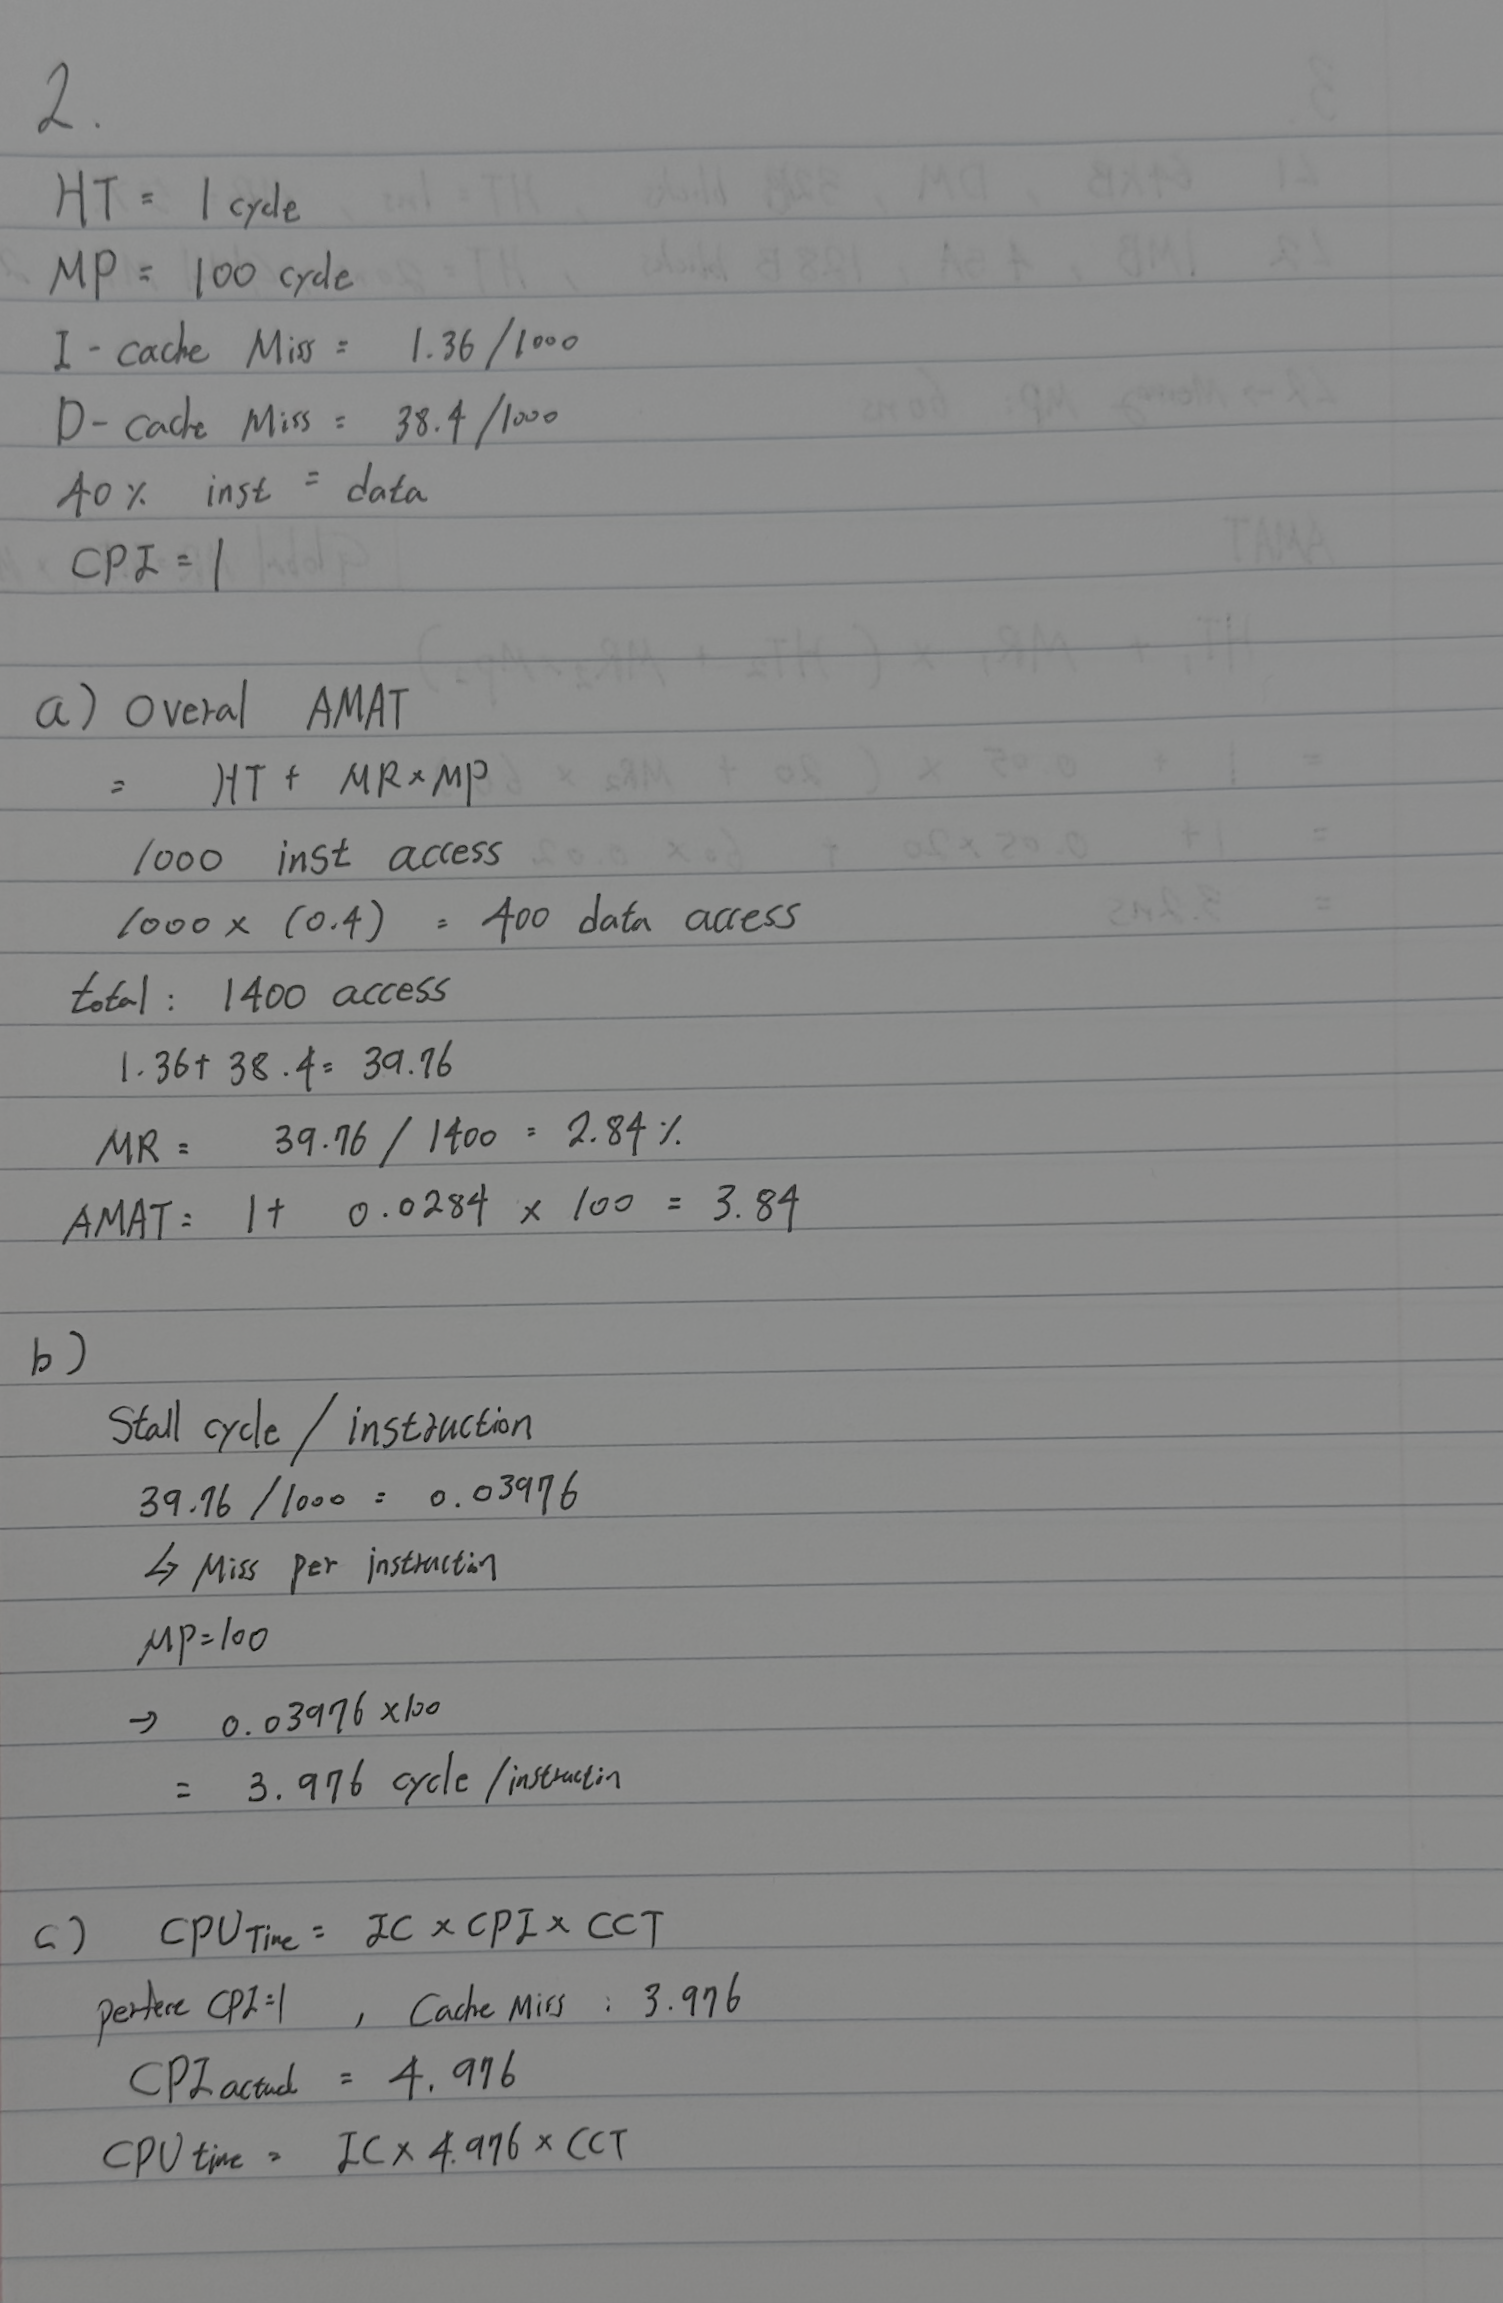
Assume we are using 32-bit address. L1 cache is direct mapped and size is 16KB, block size is 32B. L2 cache is 8-way set associative and size is 4MB,
12.Design L1, L2 caches
The main idea is that L1 and L2 have different jobs, so they are intentionally designed differently.differently.$\\boxed{\\text{L1: optimize for speed
13.Victim Caches
2. Victim Caches Victim cache holds data that has been deleted from the cache, in case it is needed again This is fully associative cache and can help to reduce misses with direct-mapped or set assoc...
14.Reducing Hit times (Not included in mid term)
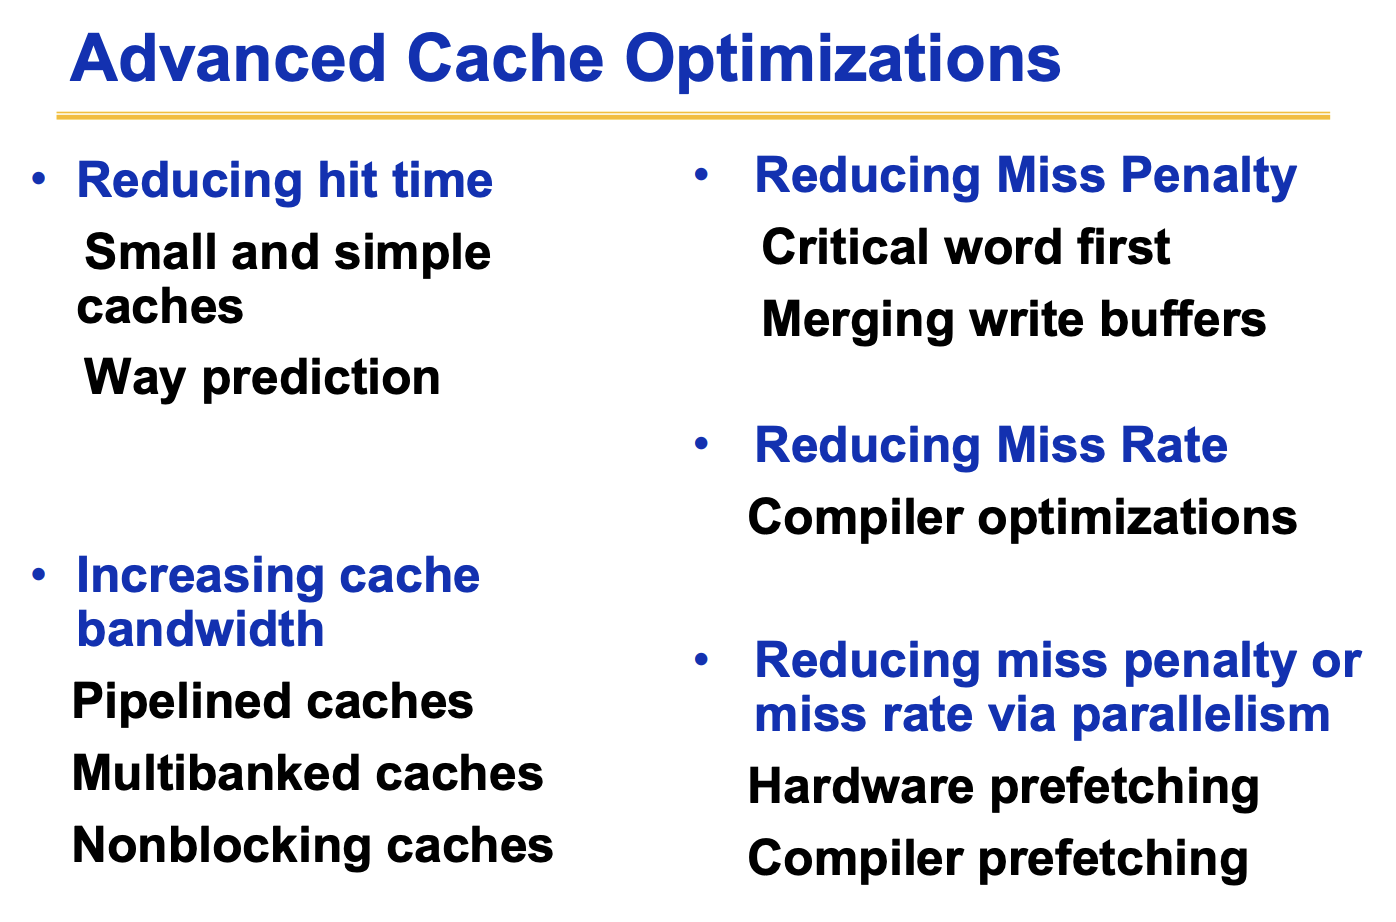
Hit time is the time to find data that is in the cache: use the index to pick a set, read its tag(s) and data, compare tags, then choose the right blo
15.Increasing Cache BandWidth (Not included in mid term)
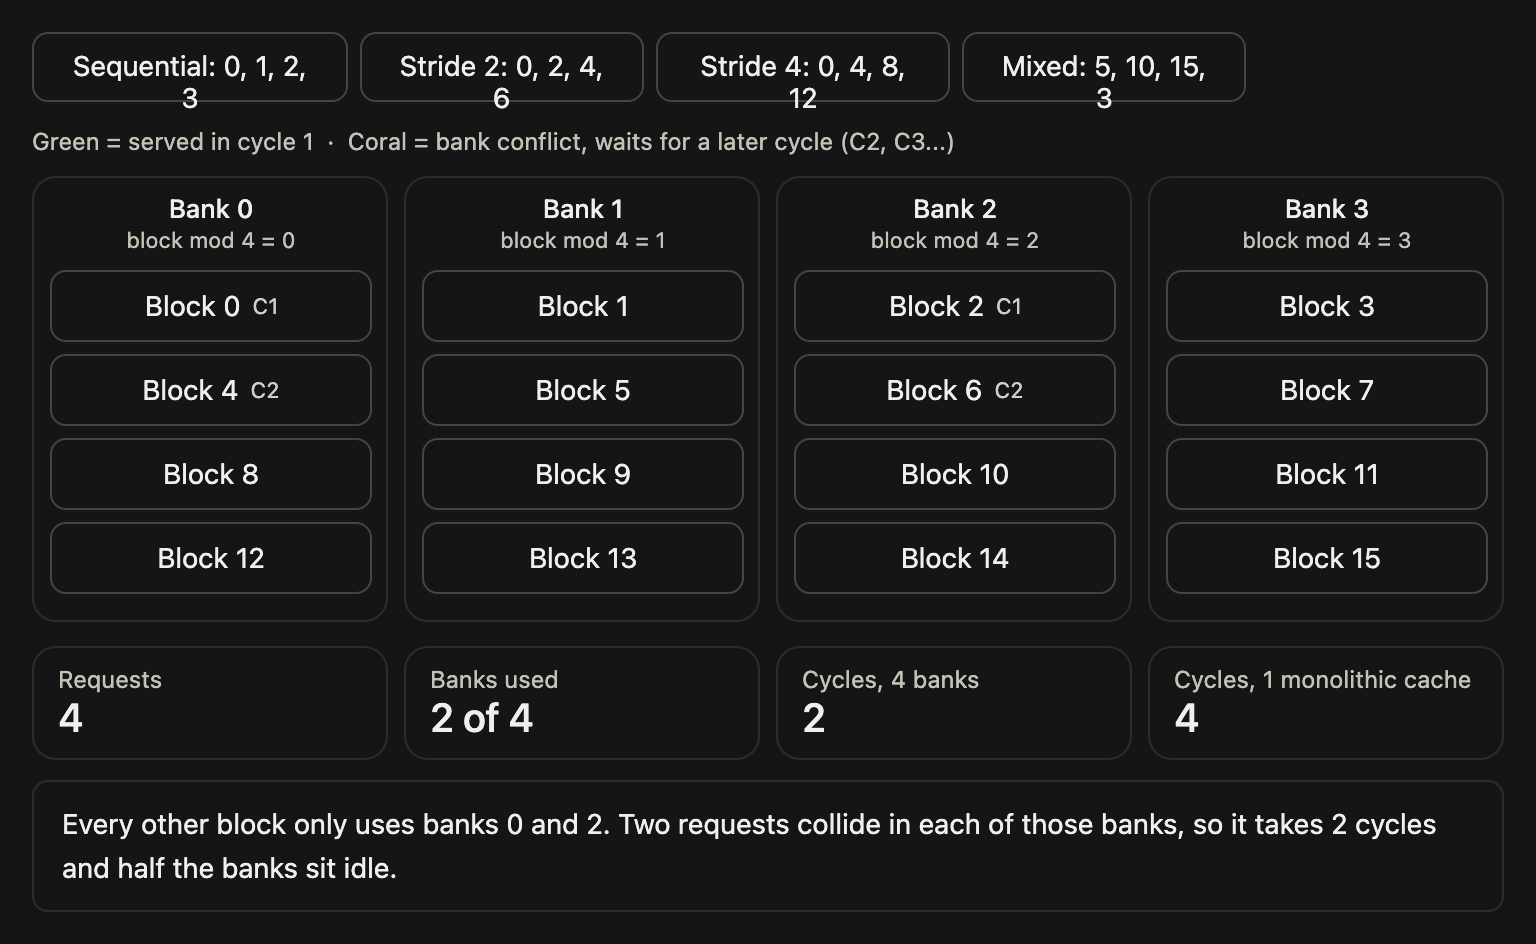
1. Pipelined caches A. Pipelining A processor's clock cycle can be no shorter than its slowest single step (the critical path). A cache access is one
16.Reducing Miss Penalty - mid term
1. Early restart, Critical Word First CPU normally needs just one word of the block at a time. Don’t wait for full block before restarting CPU Early restart — As soon as the requested word of the blo...
17.HW3 - mid term (most important)
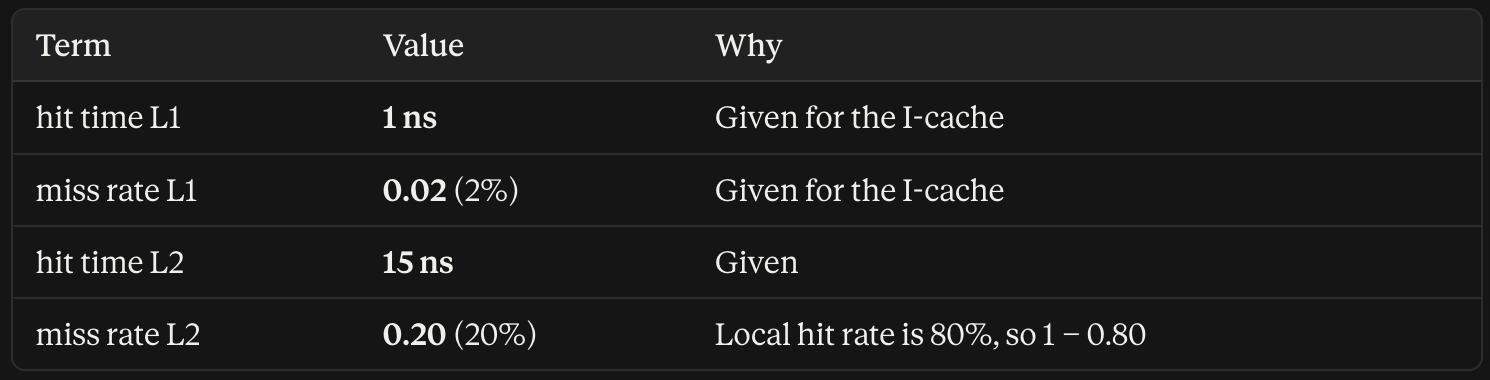
You are building a computer system around a processor with in-order execution that runs at 1 GHz and has a CPI of 1, excluding memory accesses. The on
18.Reducing Missed by Compiler Optimizations- (Final range start)
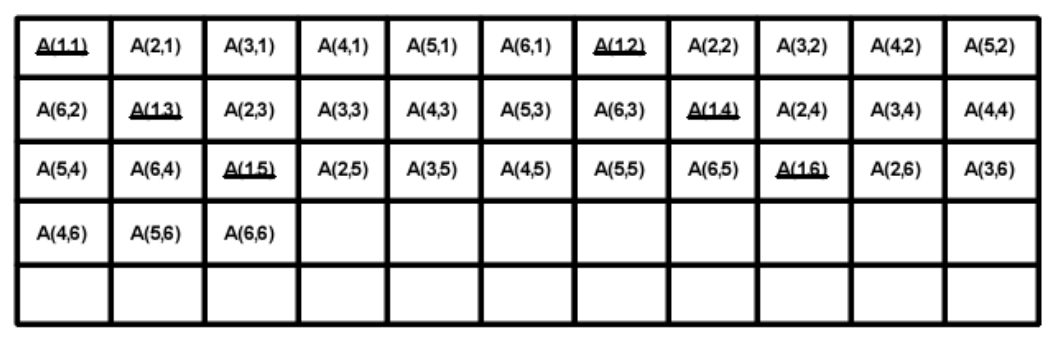
The optimized software can greatly reduce the missratesReorder procedures in memory so as to reduce conflict misses, without affecting correctnessProf
19.Hardware, Software Prefetching
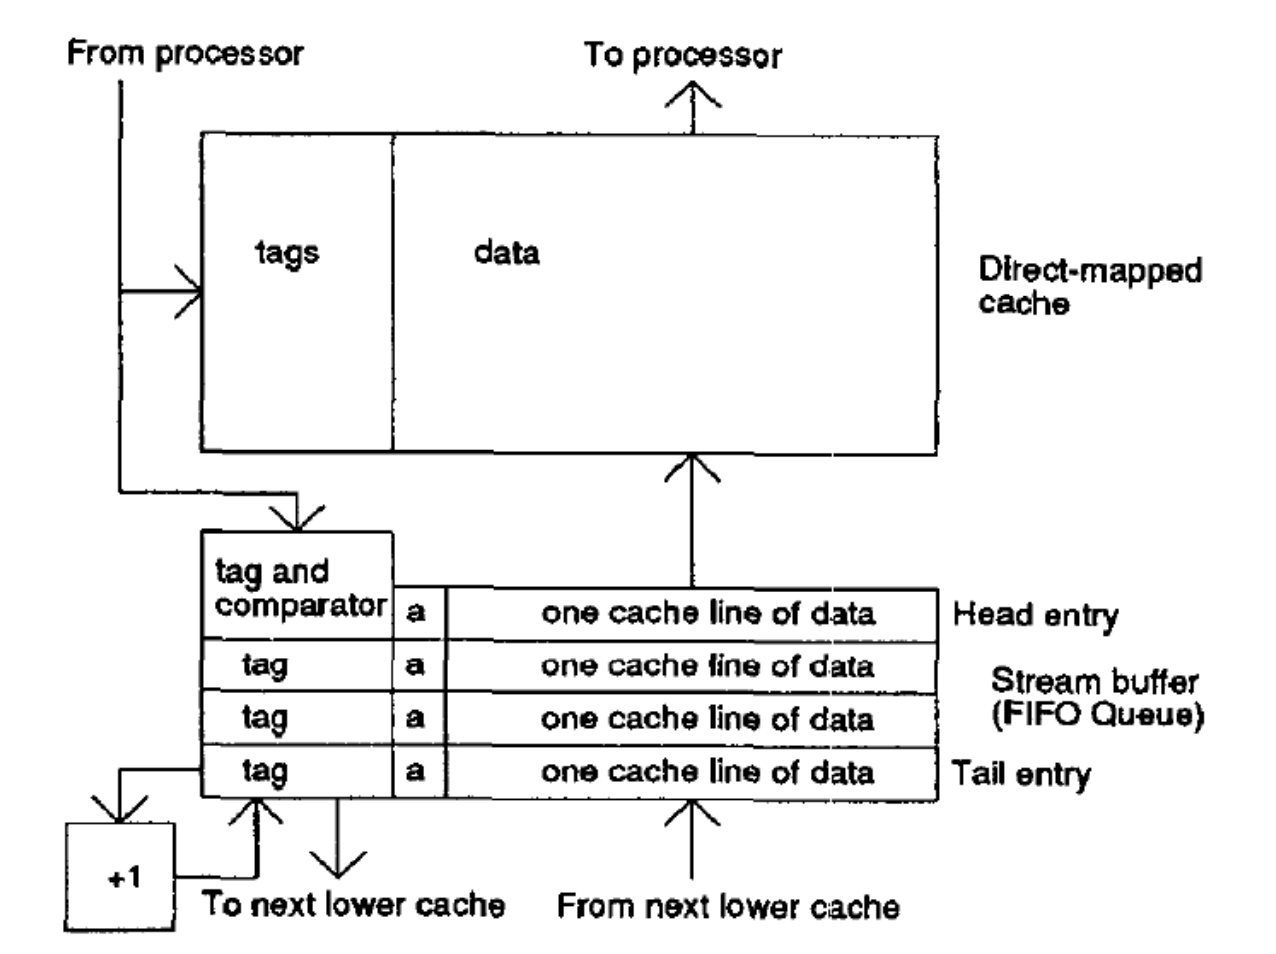
No need for programmer or compiler interventionNo changes to existing executablesTake advantage of run-time informationMajor design questionsWhat to p
20.Prefetching Exercise (Very Important)
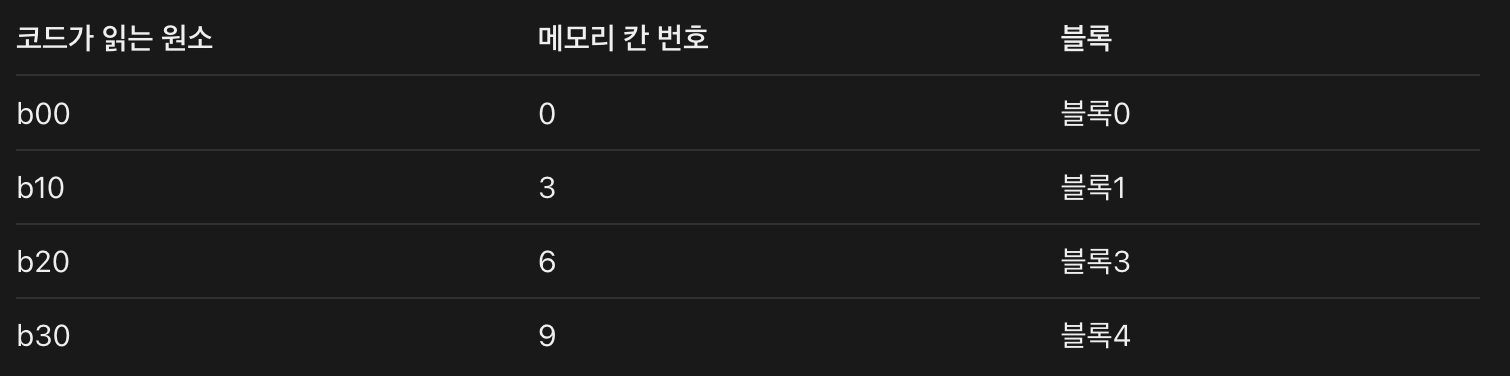
Data PrefetchRegister Prefetch: load data int registerCache Prefetch: load into cacheSpecial prefetching instructions cannot cause faults. The addr do
21.Virtual Memory
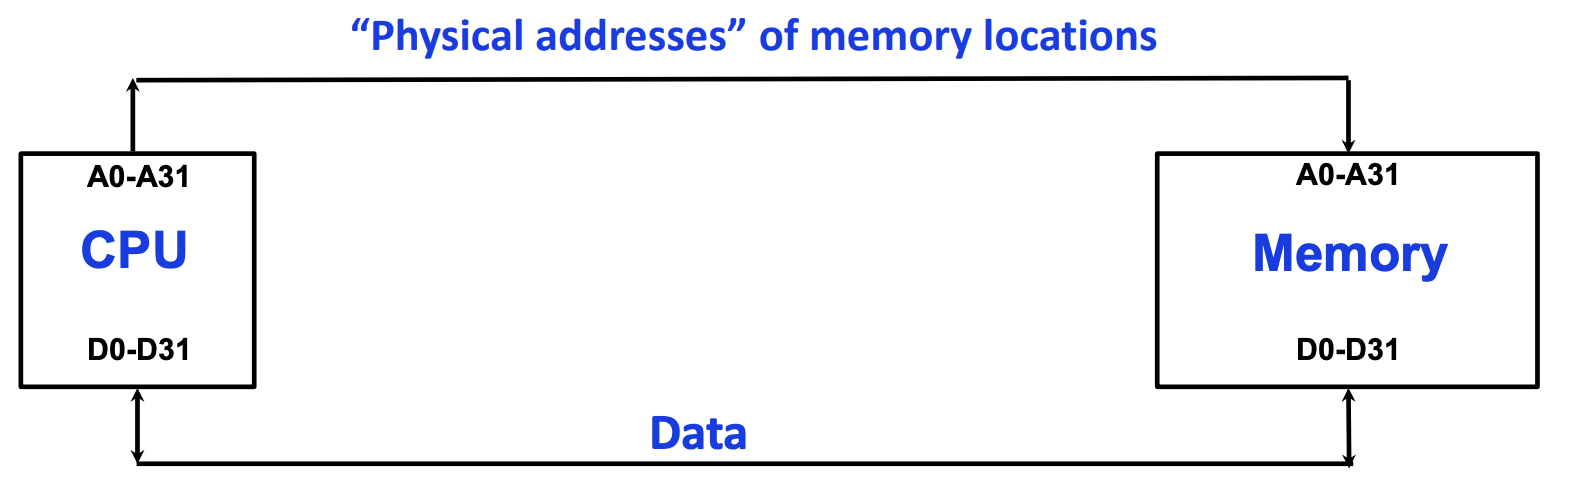
All processes share one address space: The physical address spaceWhat is the disadvantage?Too expensive to dedicate a full address space for just one
22.HW4
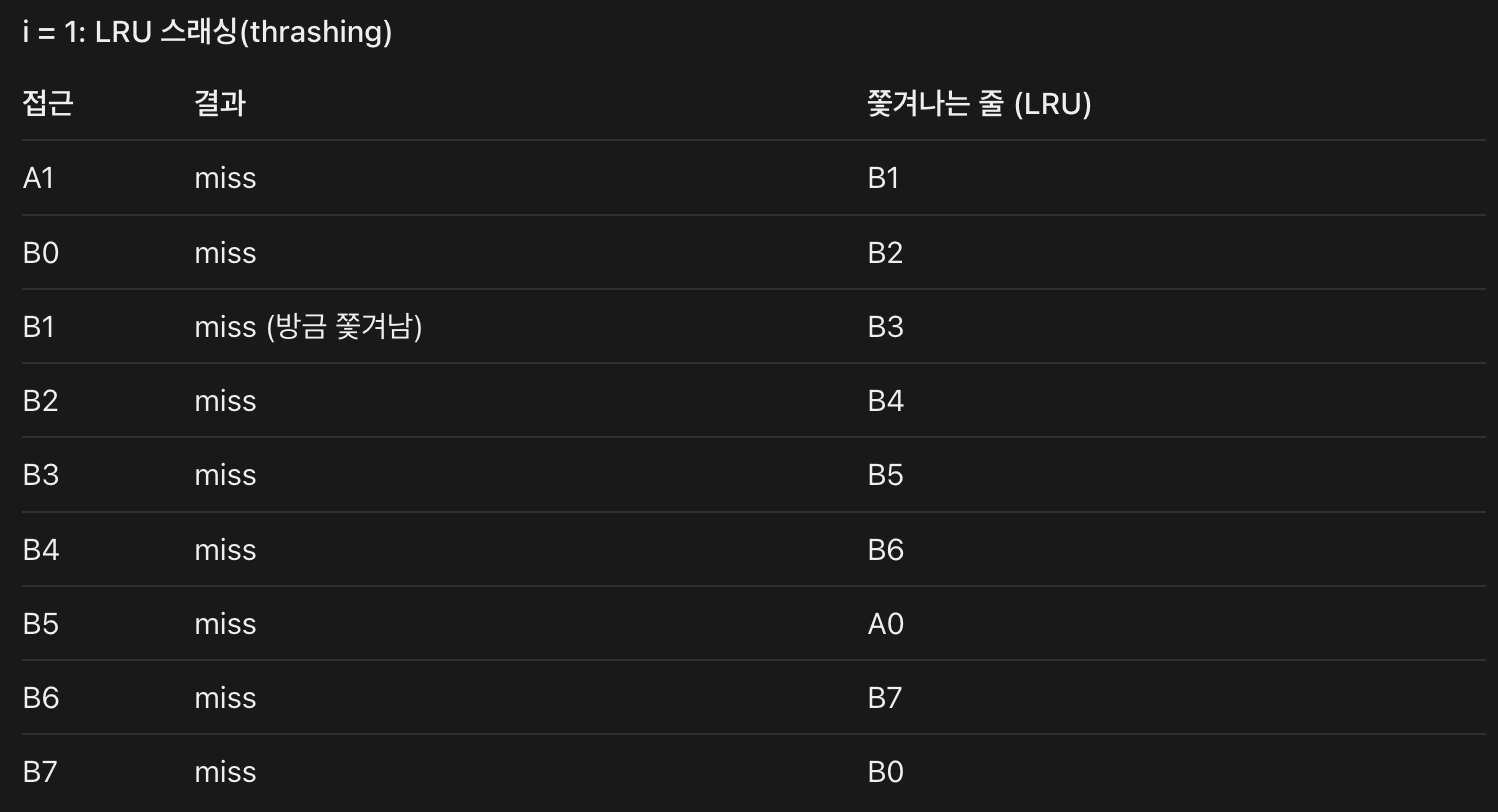
Consider the following code, which sums the elements of a product of two matrices:Assume the following:There is a perfect instruction cache; i.e., do
23.Translation Lookaside Buffer (TLB)
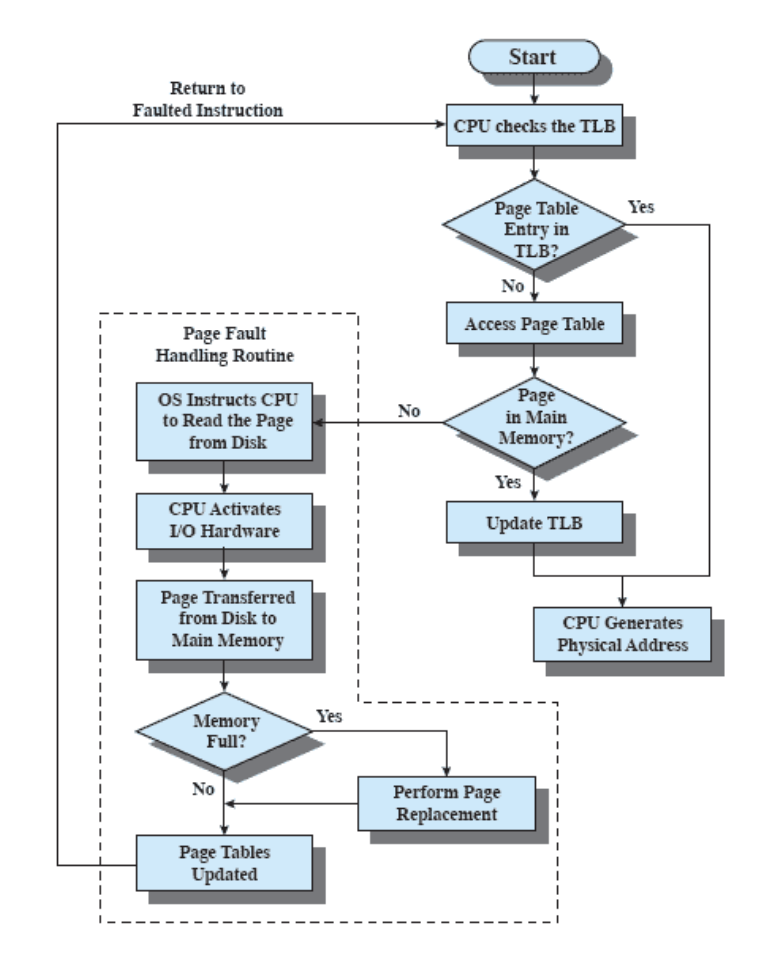
A TLB is a small, fast cache that remembers where virtual pages live in physical memory, so the CPU doesn’t have to read the page table from memory on
24.TLB Exercise
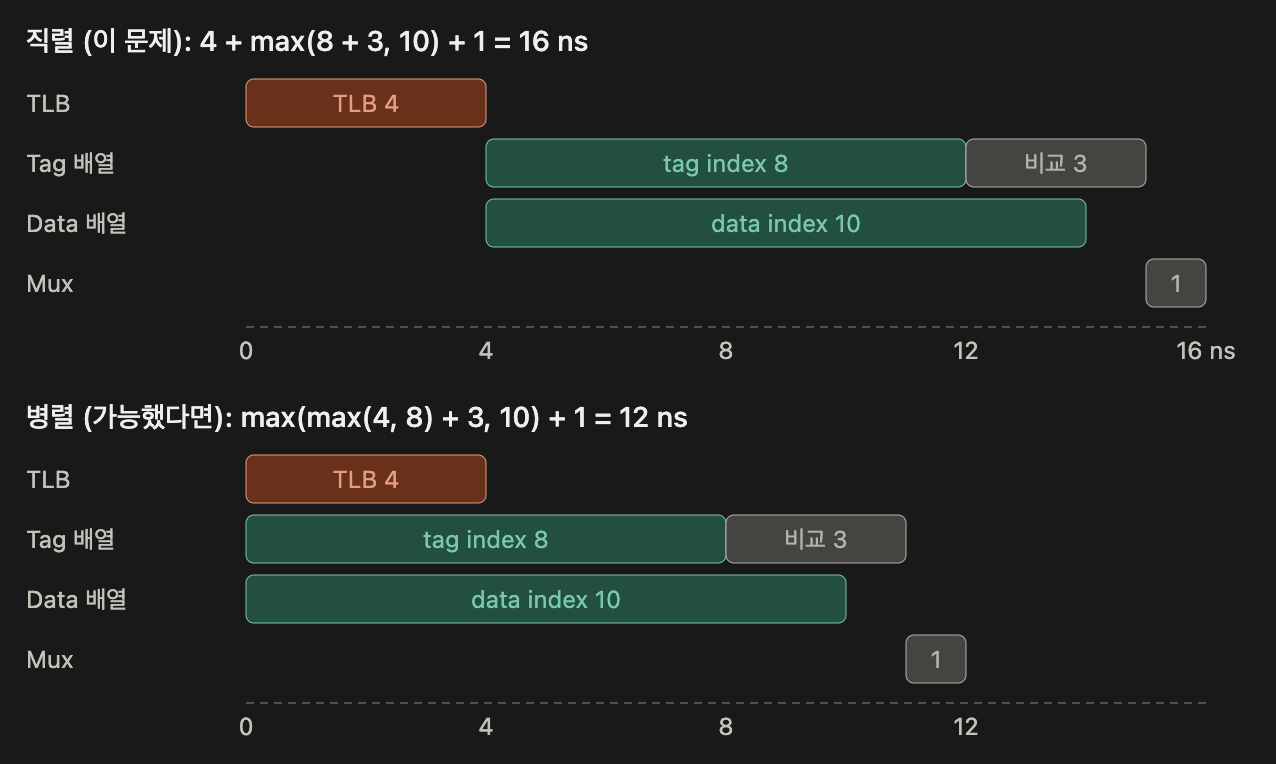
풀이 순서 (공식 5개)Consider a system with the following processor components and policies:A direct-mapped L1 data cache of size 4KB and block size of 16 byt
25.Multiprocessors
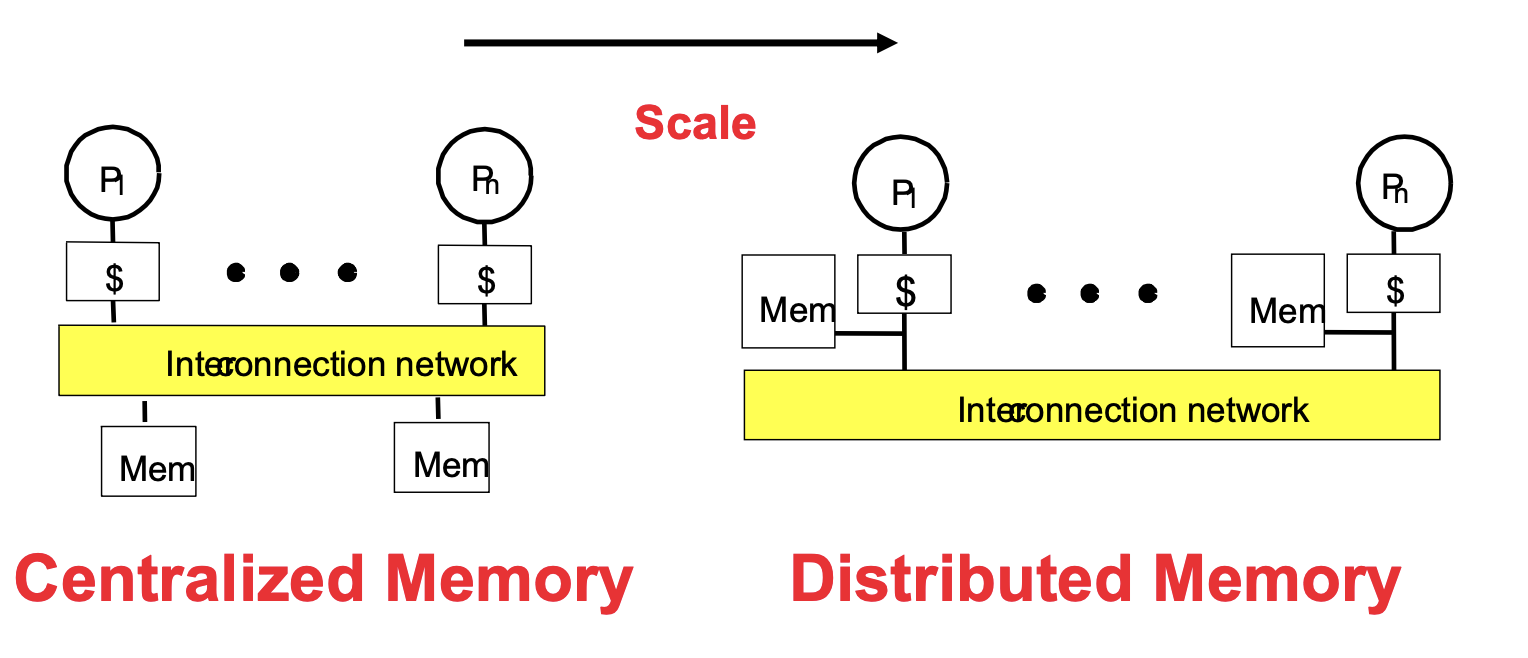
Growth in data-intensive applicationsData bases, file servers, …Growing interest in servers, server perf.Improved understanding in how to use multipro