논문 리뷰
1.[논문 리뷰] DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model
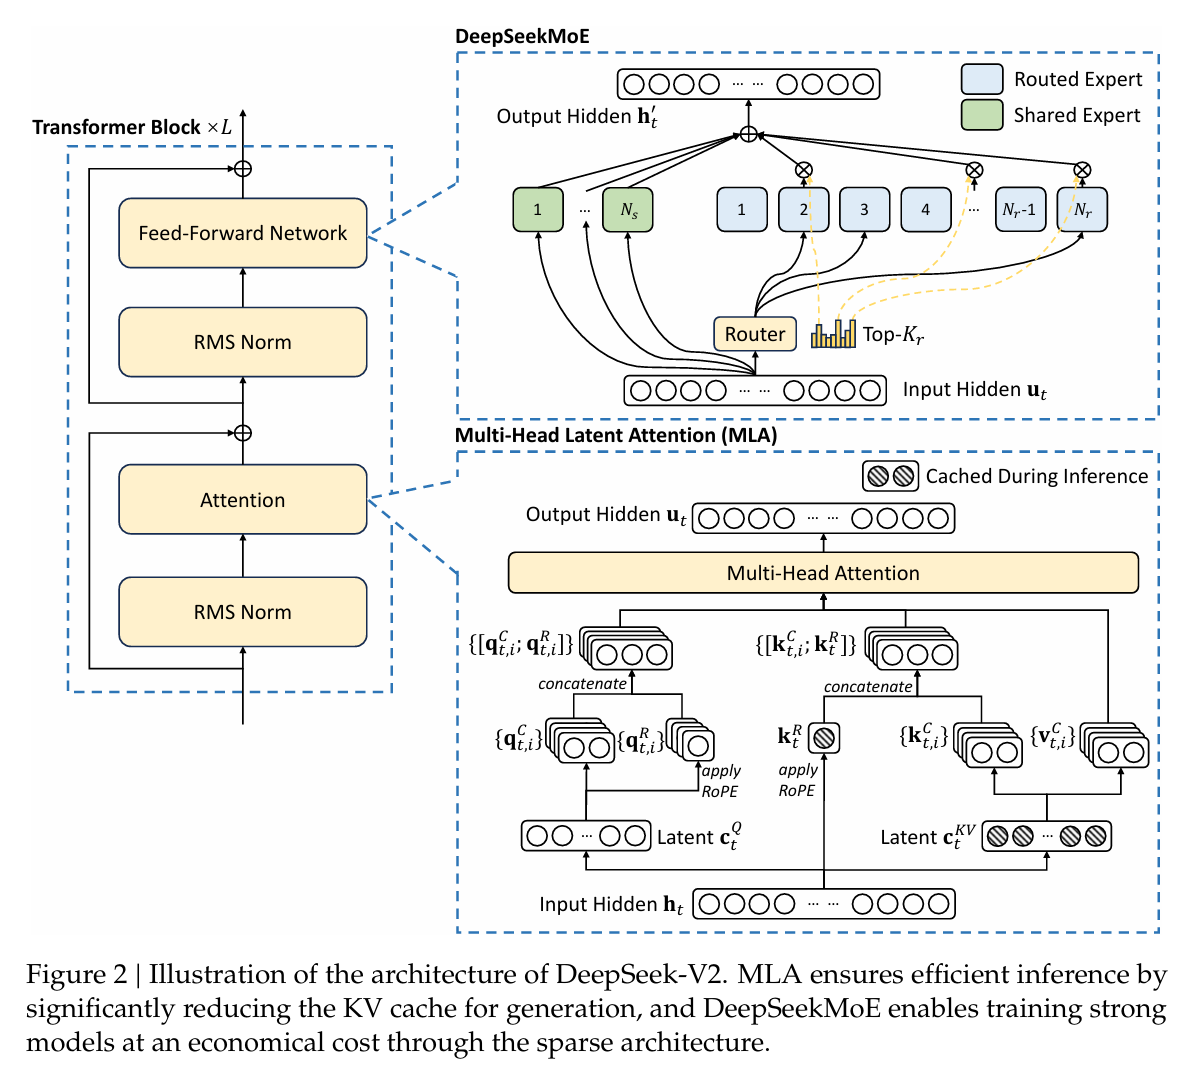
DeepSeek-V2는 K와 V를 latent vector로 압축하는 MLA와 Routed expert, Shared expert를 구분하는 MoE 방식으로 high inference efficiency와 low training cost를 보였다
2026년 9월 24일
2.[논문 리뷰] Fast Transformer Decoding: One Write-Head is All You Need
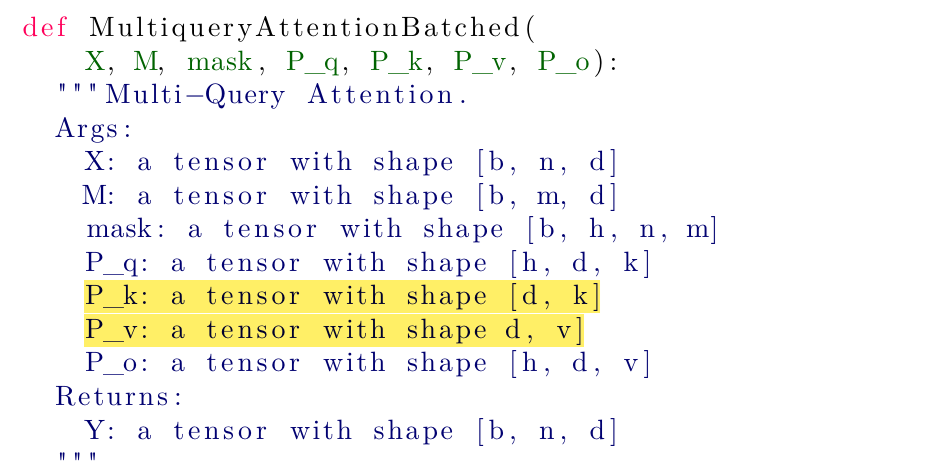
MQA(Multi-Query Attention)는 Query는 head마다 다르게 두고 Key와 Value는 모든 head가 동일한 값을 공유하여 incremental decoding step을 가속화한다.
2026년 9월 25일
3.[논문 리뷰] GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints
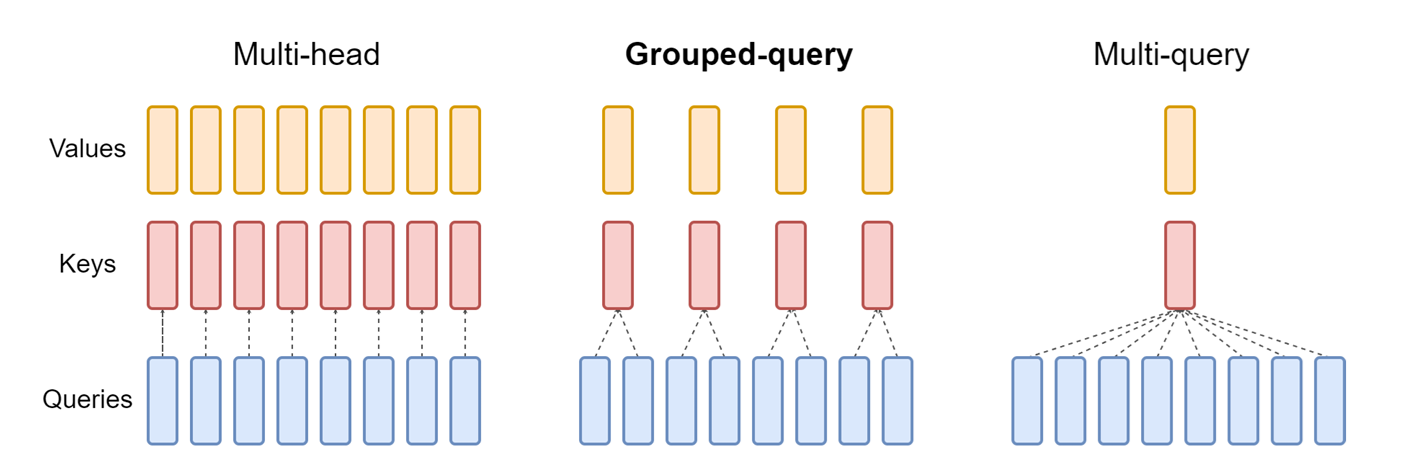
GQA(Grouped Query Attention)은 Query head를 G개의 그룹으로 나누고 각 그룹마다 동일한 K, V head 하나를 공유하는 방식이다.
2026년 9월 26일
4.[논문 리뷰] Transformers are RNNs: Fast Autoregressive Transformers with Linear Attention
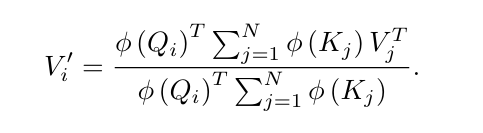
Linear attention은 kernel feature map을 통해 메모리와 시간복잡도를 O(N)으로 만든다.
2026년 9월 29일
5.[논문 리뷰] ROFORMER: Enhanced Transformer with Rotary Position Embedding
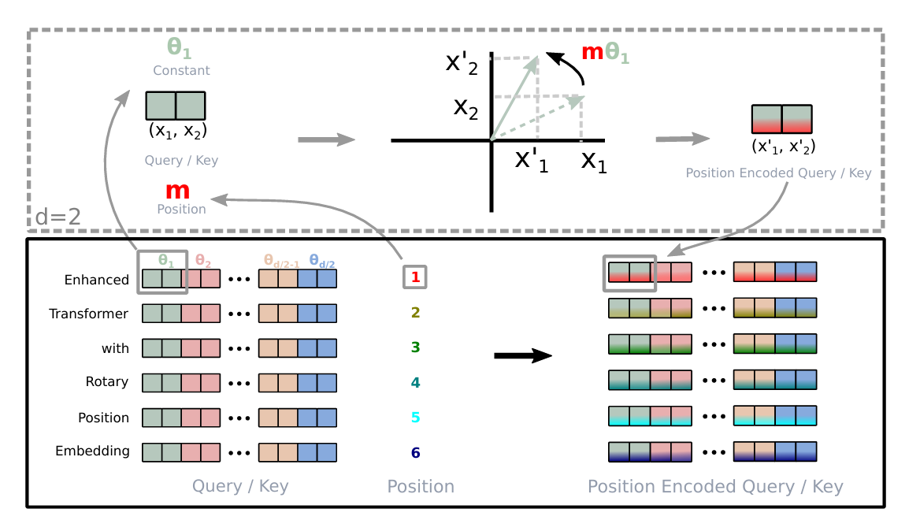
Roformer는 position 정보를 더하던 기존 방식들과 달리 회전 행렬을 곱하는 RoPE 방식을 도입하였다.
2026년 9월 30일
6.[논문 리뷰] Scaling Laws for Neural Language Models
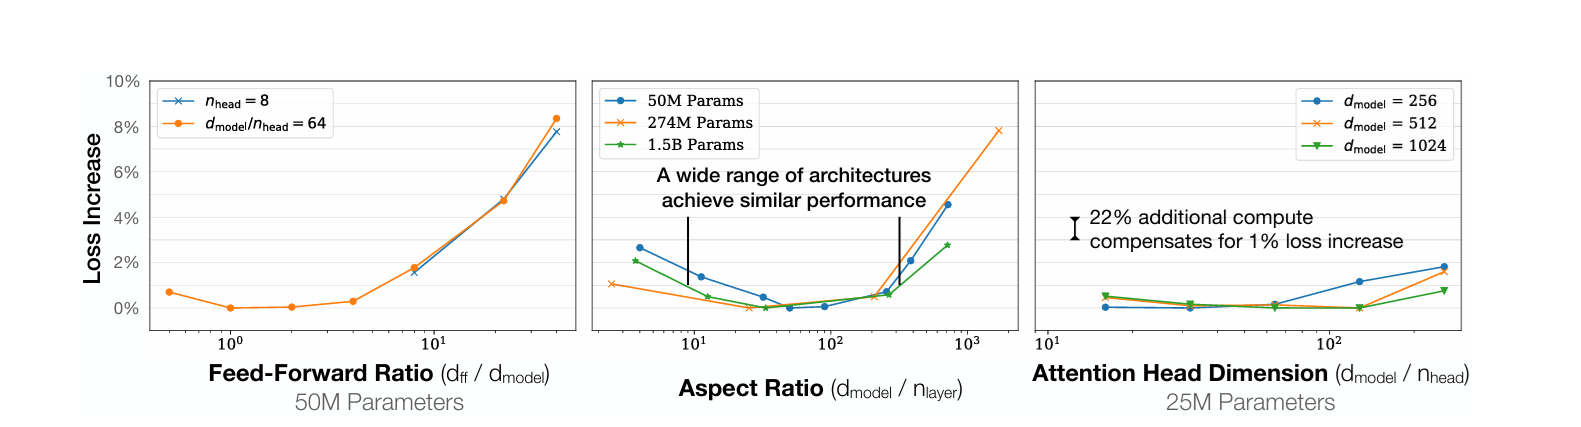
LLM의 성능을 compute, parameter, dataset size에 대한 power law로 나타낼 수 있다
5일 전